Researcher at Kling AI

Yizeng Han

韩益增

Building intelligent and efficient video generation models towards multimodal AGI.

Ph.D. from Tsinghua University, advised by Gao Huang and Shiji Song.
Yizeng Han

About

I’m currently at Kling AI, where I work on video generation model pretraining.

During my Ph.D. at Tsinghua University, I studied dynamic neural networks for efficient visual recognition, including early exiting and spatially adaptive computation.

After my Ph.D., I worked on efficient image and video generation at Alibaba DAMO Academy, including dynamic diffusion transformers, few-step distillation, and long-video generation.

Experience and education

Research Experience

Present Kling AI Video generation research
2024–26 Research Scientist Alibaba DAMO Academy
2023 Research Intern, Megvii Foundation Model Group · Advisor: Xiangyu Zhang
2017 Research Intern, Georgia Tech Advisor: Gregory D. Abowd

Education

2018–24 Ph.D., Tsinghua University Automation
2014–18 B.E., Tsinghua University Automation
Honors and awards
  • 2024First Prize, CSIG Natural Science Award · 中国图象图形学会自然科学奖一等奖(第四完成人)
  • 2024Outstanding Doctoral Dissertation · Tsinghua University
  • 2024Outstanding Graduate · Tsinghua University
  • 2024Outstanding Graduate of Beijing · Beijing Municipal Education Commission
  • 2023Comprehensive Excellence Scholarship · Tsinghua University
  • 2022National Scholarship · Ministry of Education of China
  • 2017Comprehensive Excellence Scholarship · Tsinghua University
  • 2016Comprehensive Excellence Scholarship · Tsinghua University
  • 2015Academic Excellence Scholarship · Tsinghua University

Selected research

All publications
DyDiT++
IEEE TPAMI, 2026

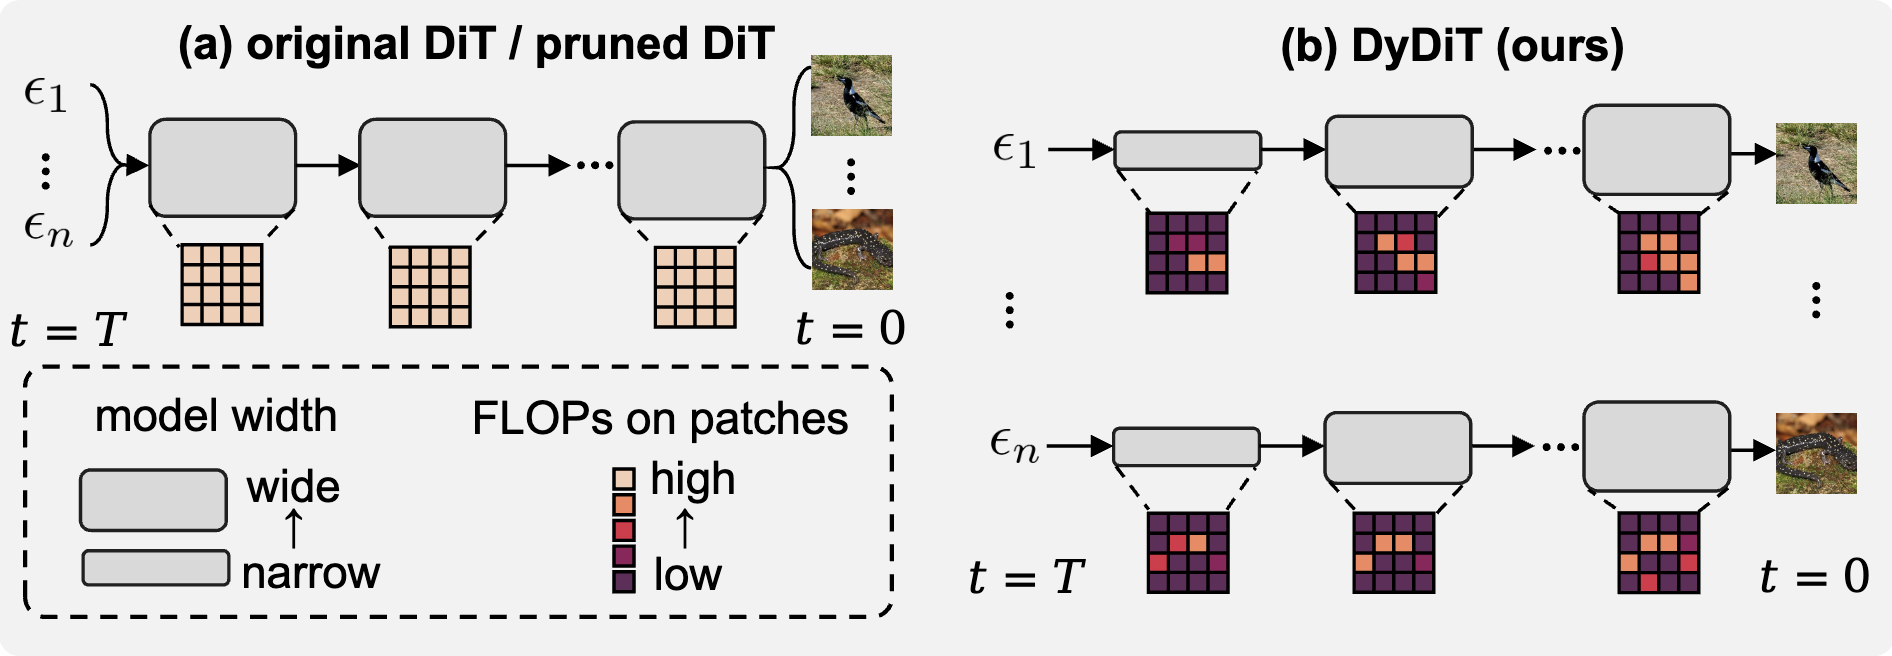
DyDiT++: Diffusion Transformers with Timestep and Spatial Dynamics for Efficient Visual Generation

Wangbo Zhao*, Yizeng Han*, Jiasheng Tang, Kai Wang, Hao Luo, Yibing Song, Gao Huang, Fan Wang, Yang You

We extend DyDiT to T2I (DyFLUX) and video generation. Moreover, LoRA finetuning is supported.

RAPID^3
ICLR, 2026

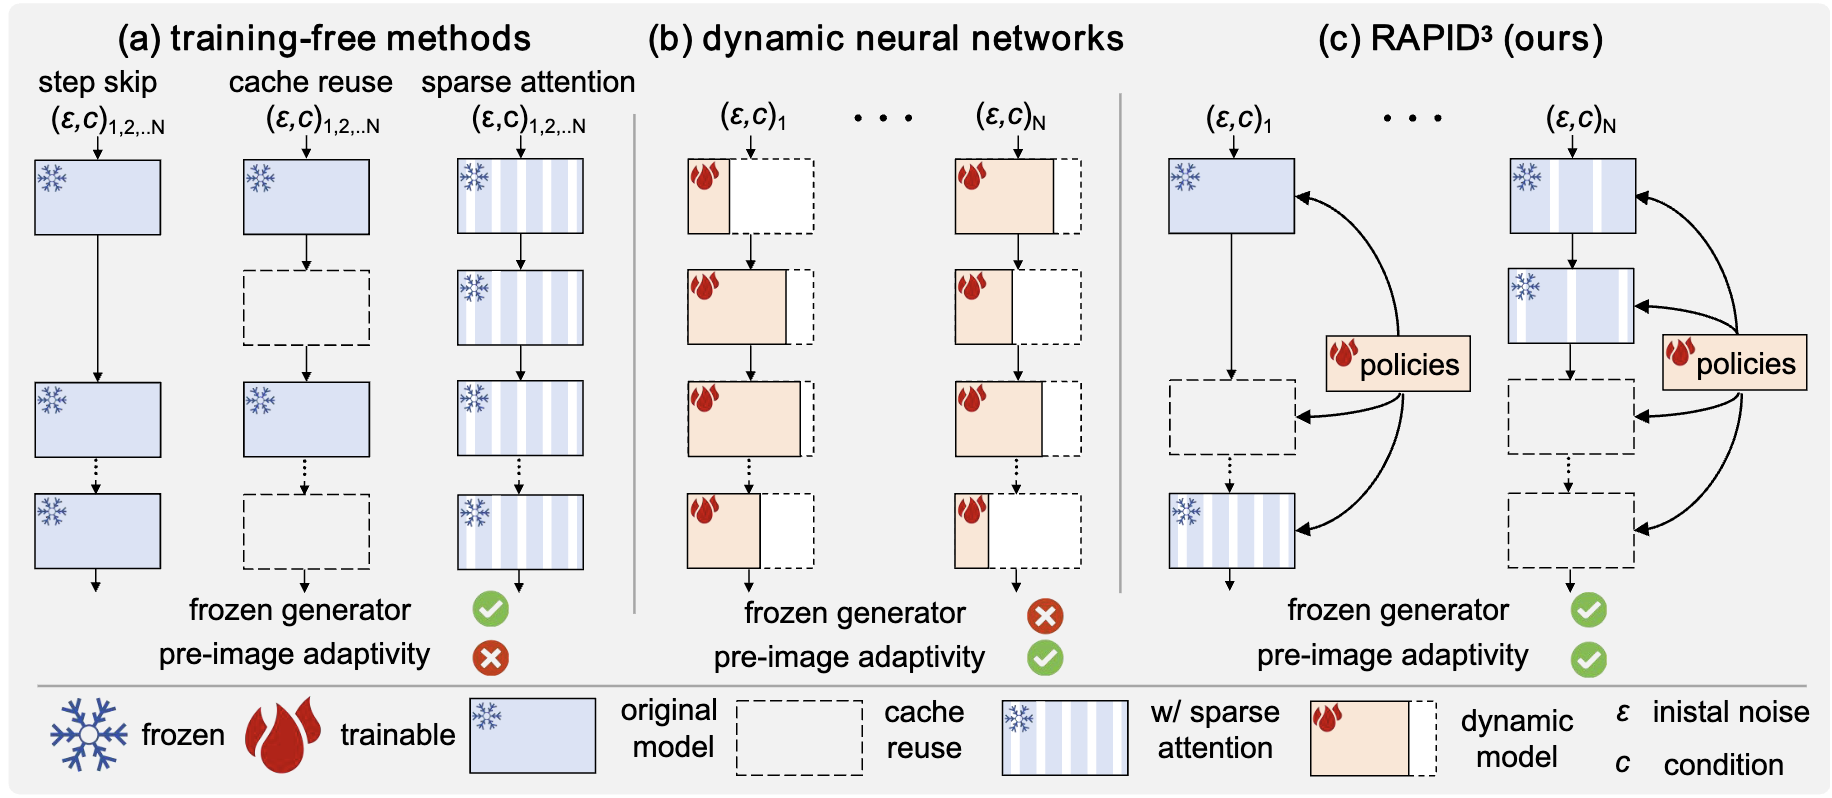
RAPID^3: Tri-Level Reinforced Acceleration Policies for Diffusion Transformer

Wangbo Zhao, Yizeng Han, Zhiwei Tang, Jiasheng Tang, Pengfei Zhou, Kai Wang, Bohan Zhuang, Zhangyang Wang, Fan Wang, Yang You
SGL
CVPR, 2025

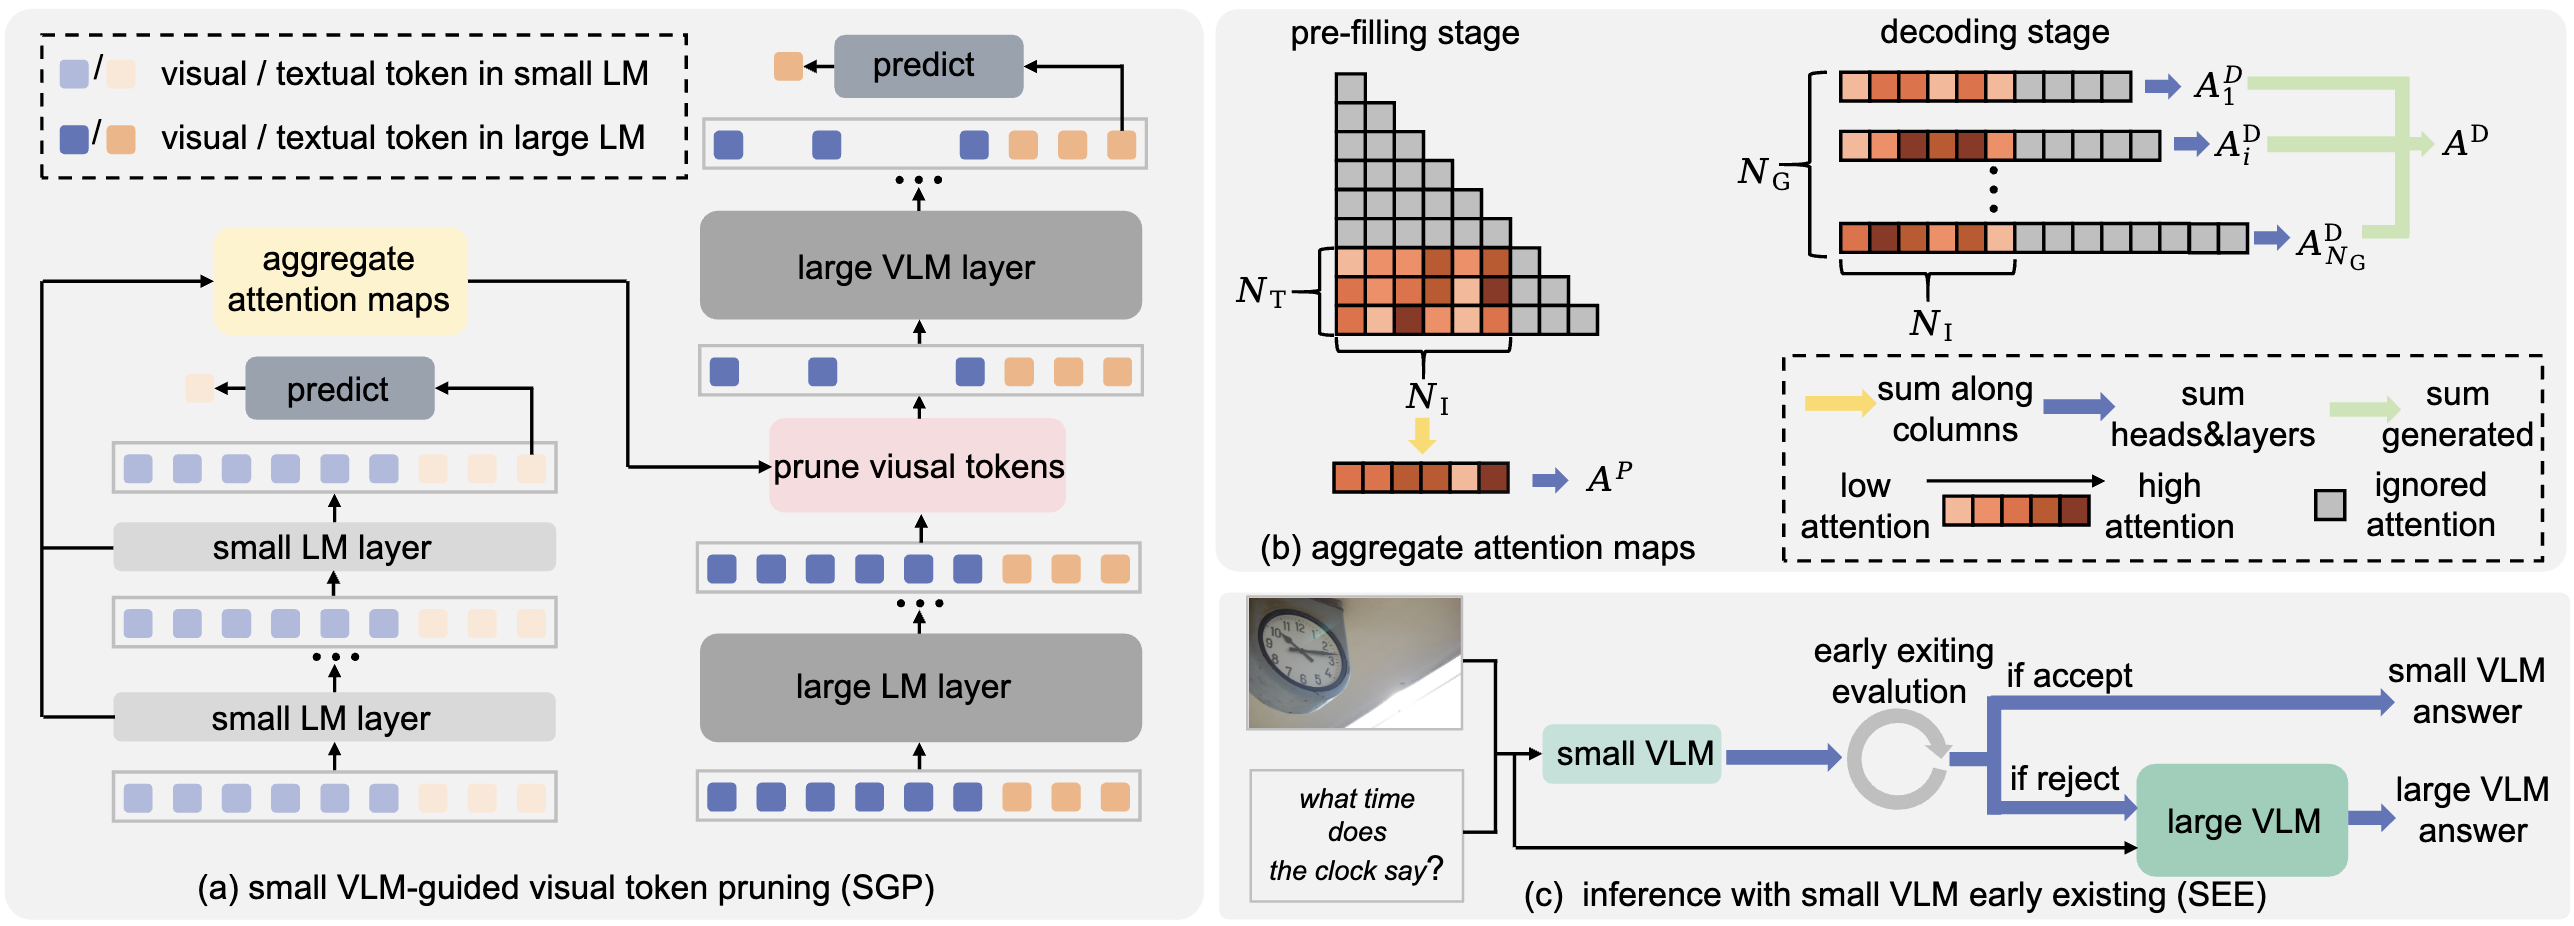
A Stitch in Time Saves Nine: Small VLM is a Precise Guidance for accelerating Large VLMs

Wangbo Zhao*, Yizeng Han*, Jiasheng Tang, Zhikai Li, Yibing Song, Kai Wang, Zhangyang Wang, Yang You

Recent work

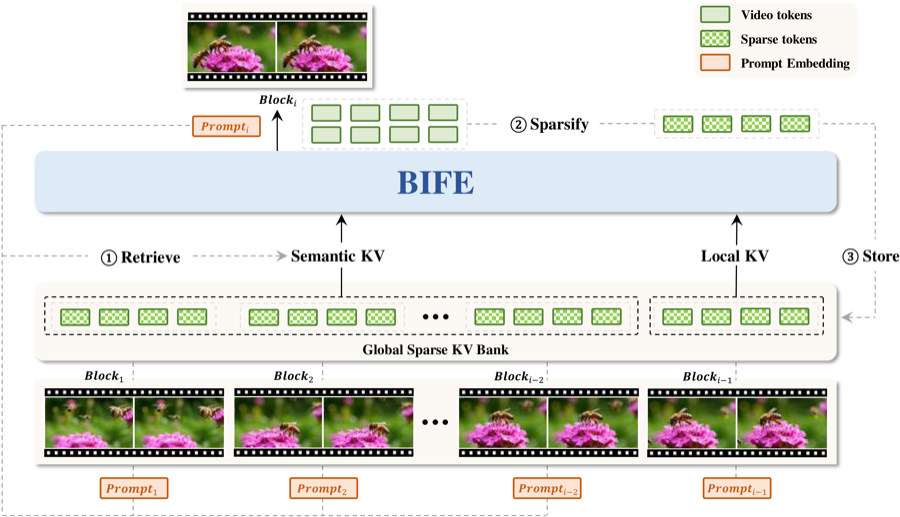
BIFE framework with local and global sparse KV caches
SIGGRAPH Asia 2026 Technical Communications

BIFE: Better Interaction, Fewer Errors for Minute-Long Video Generation

Zeyu Zhang*, Jinyuan Mao*, Shuning Chang, Yuanyu He, Yizeng Han, Jiasheng Tang, Fan Wang, Bohan Zhuang

BIFE combines sparse KV cache retrieval and block forcing to preserve long-range interactions and reduce drift in minute-long video generation.

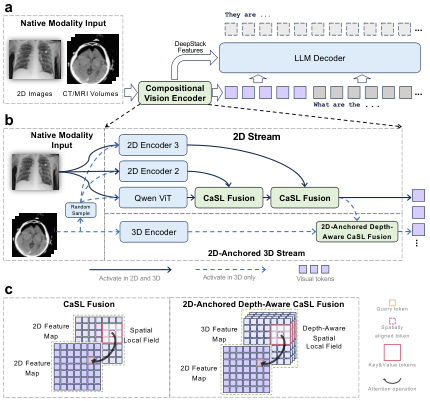
ClinFusion architecture for 2D and 3D medical images
arXiv preprint, 2026

ClinFusion: A Vision-Centric Multimodal LLM System for Holistic Medical Understanding

Hangjie Yuan*, Yichen Qian*, Zhiwei Tang*, Xianzhe Xu*, Sicheng Yang, Lirong Wu, Jinwang Wang, Pengju Wang, Zhitao Zeng, Yizeng Han, Yan Xing, Shengxuan Luo, Tao Feng, Qing Xie, Weigen Yao, Yi Yang, Zuozhu Liu, Jiasheng Tang, Xiaomao Yu, Shaocheng Wang, Jitao Wang, Jiahong Dong, Weihua Chen, Feng Xu, Fan Wang

ClinFusion combines native 2D and 3D medical image understanding in a unified vision encoder and introduces region-grounded evaluation for clinical reports.

Agent-as-a-Router
arXiv preprint, 2026

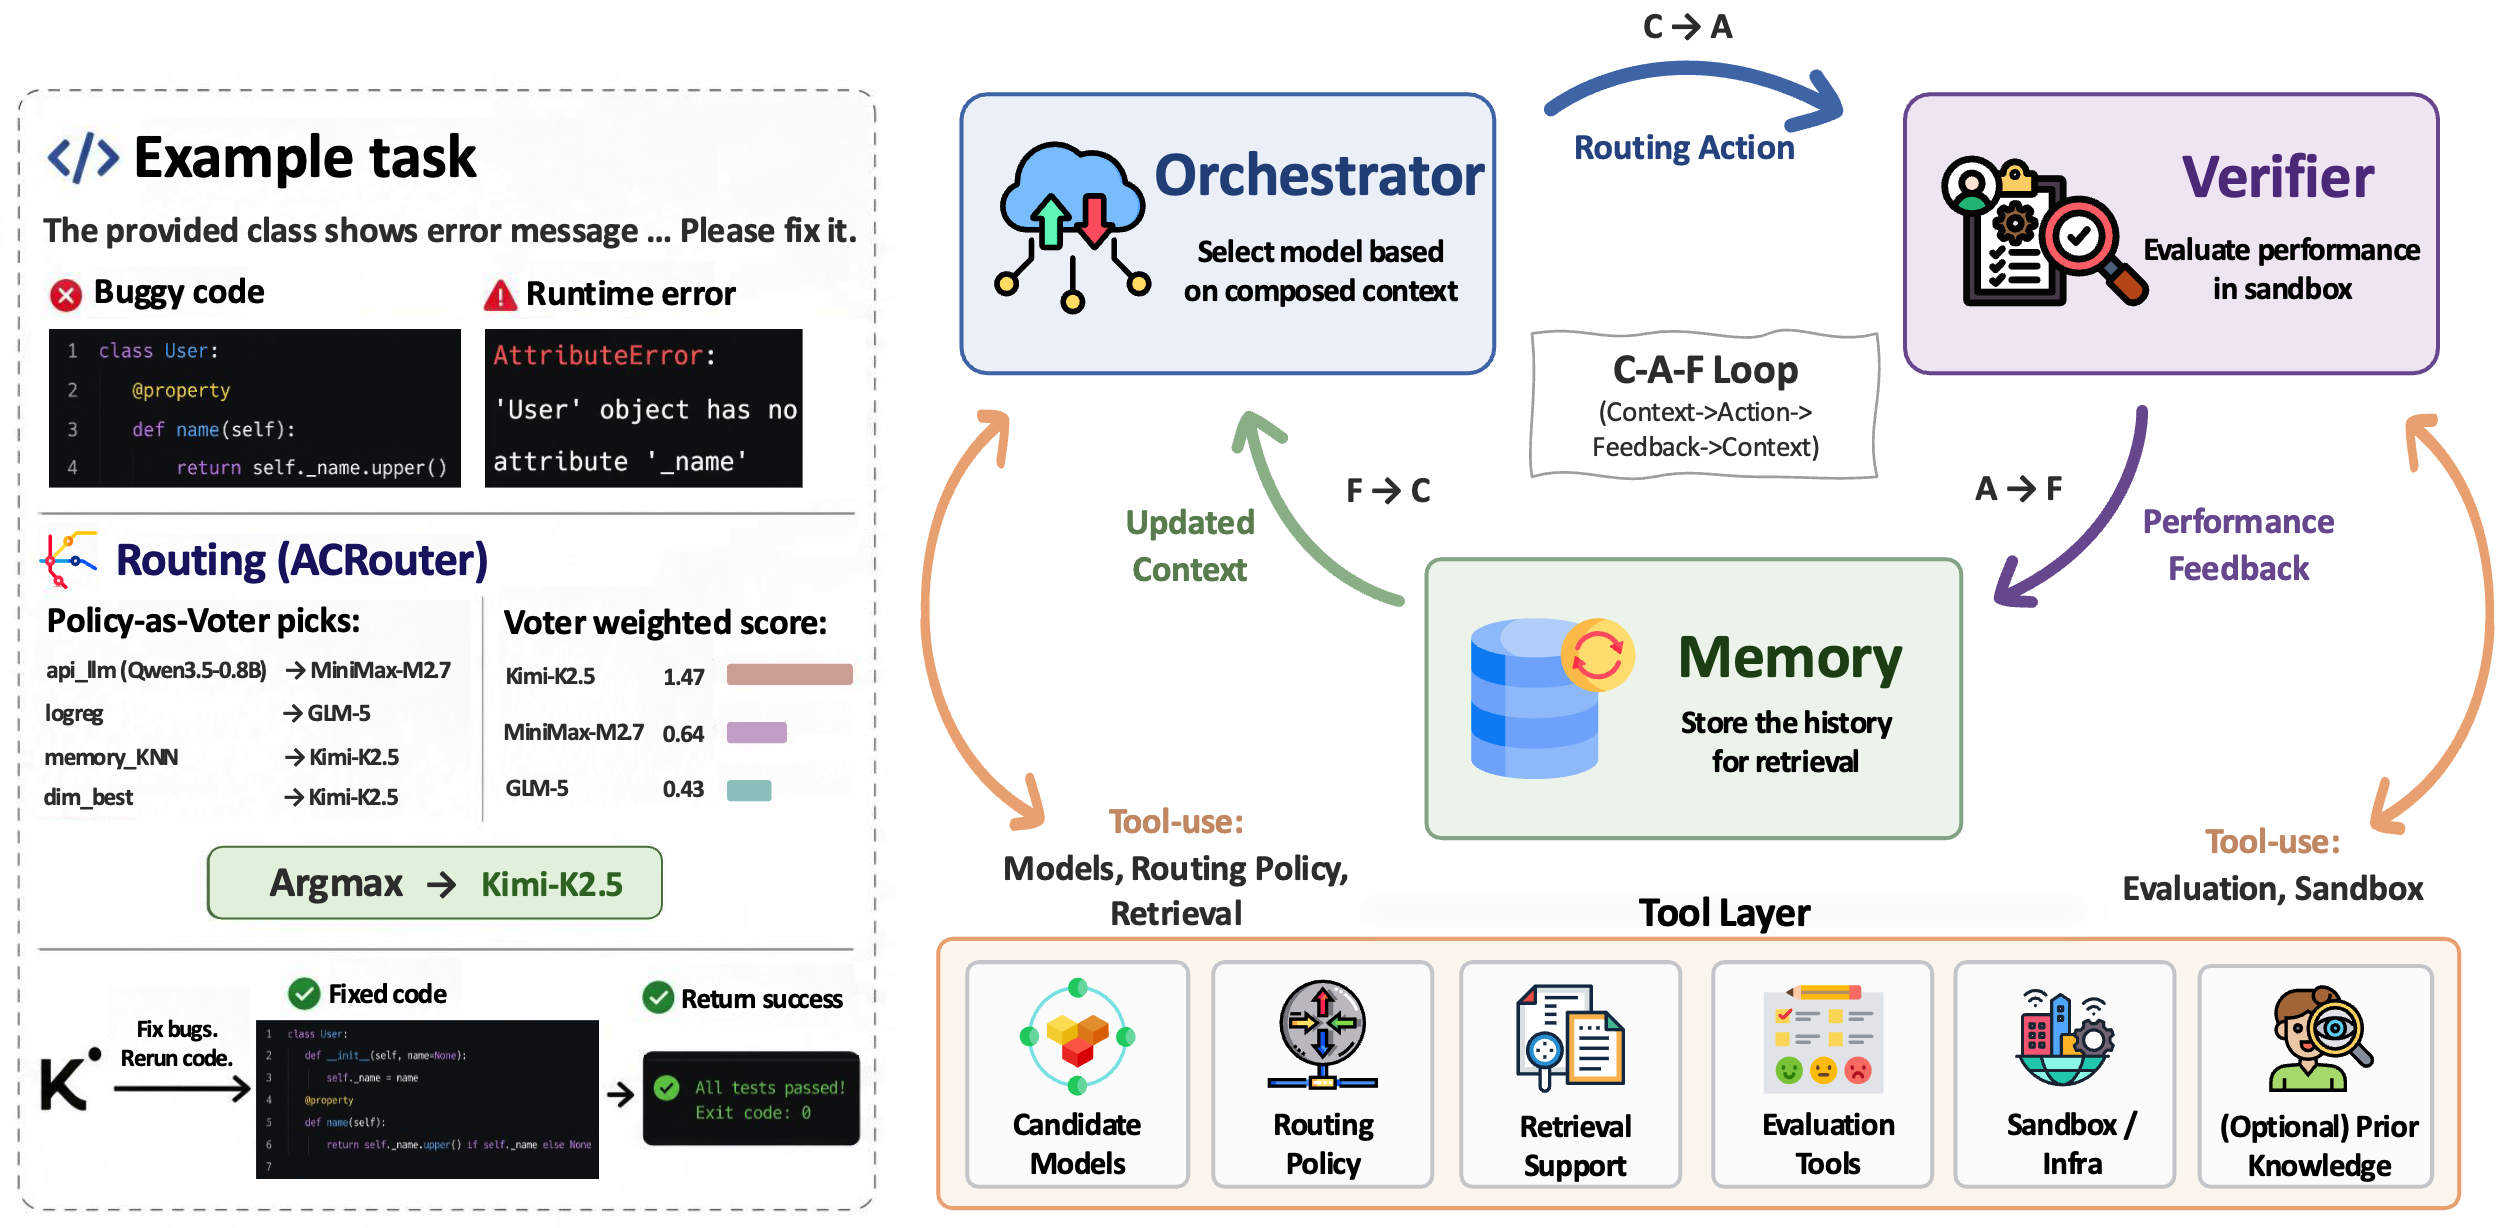
Agent-as-a-Router: Agentic Model Routing for Coding Tasks

Pengfei Zhou, Zhiwei Tang, Yixing Ma, Jiasheng Tang, Yizeng Han, Zhenglin Wan, Fanqing Meng, Wei Wang, Bohan Zhuang, Wangbo Zhao, Yang You

We formulate model routing as an agentic Context-Action-Feedback loop and introduce ACRouter and CodeRouterBench for efficient routing across frontier LLMs on coding tasks.

K-Forcing
arXiv preprint, 2026

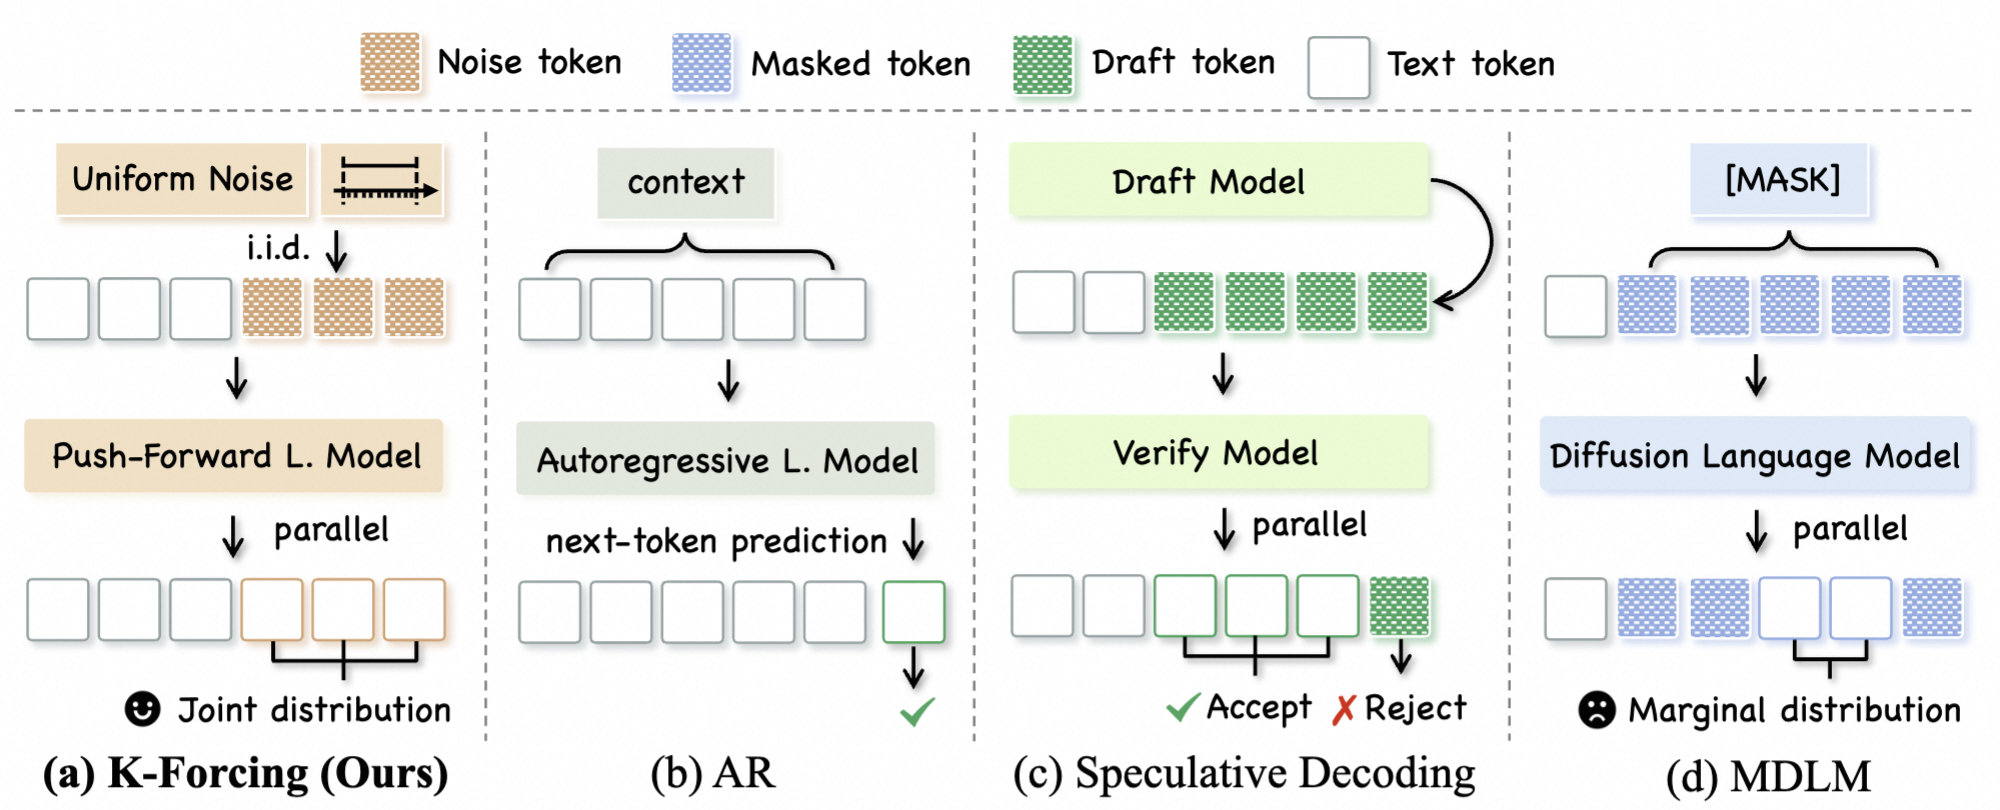
K-Forcing: Joint Next-K-Token Decoding via Push-Forward Language Modeling

Zhiwei Tang, Yuanyu He, Yizeng Han, Wangbo Zhao, Jiasheng Tang, Fan Wang, Bohan Zhuang

K-Forcing learns a push-forward language model for joint next-k-token decoding, achieving about 2.4-3.5x batch-serving speedup while reusing the autoregressive backbone.

MeshToken
arXiv preprint, 2026

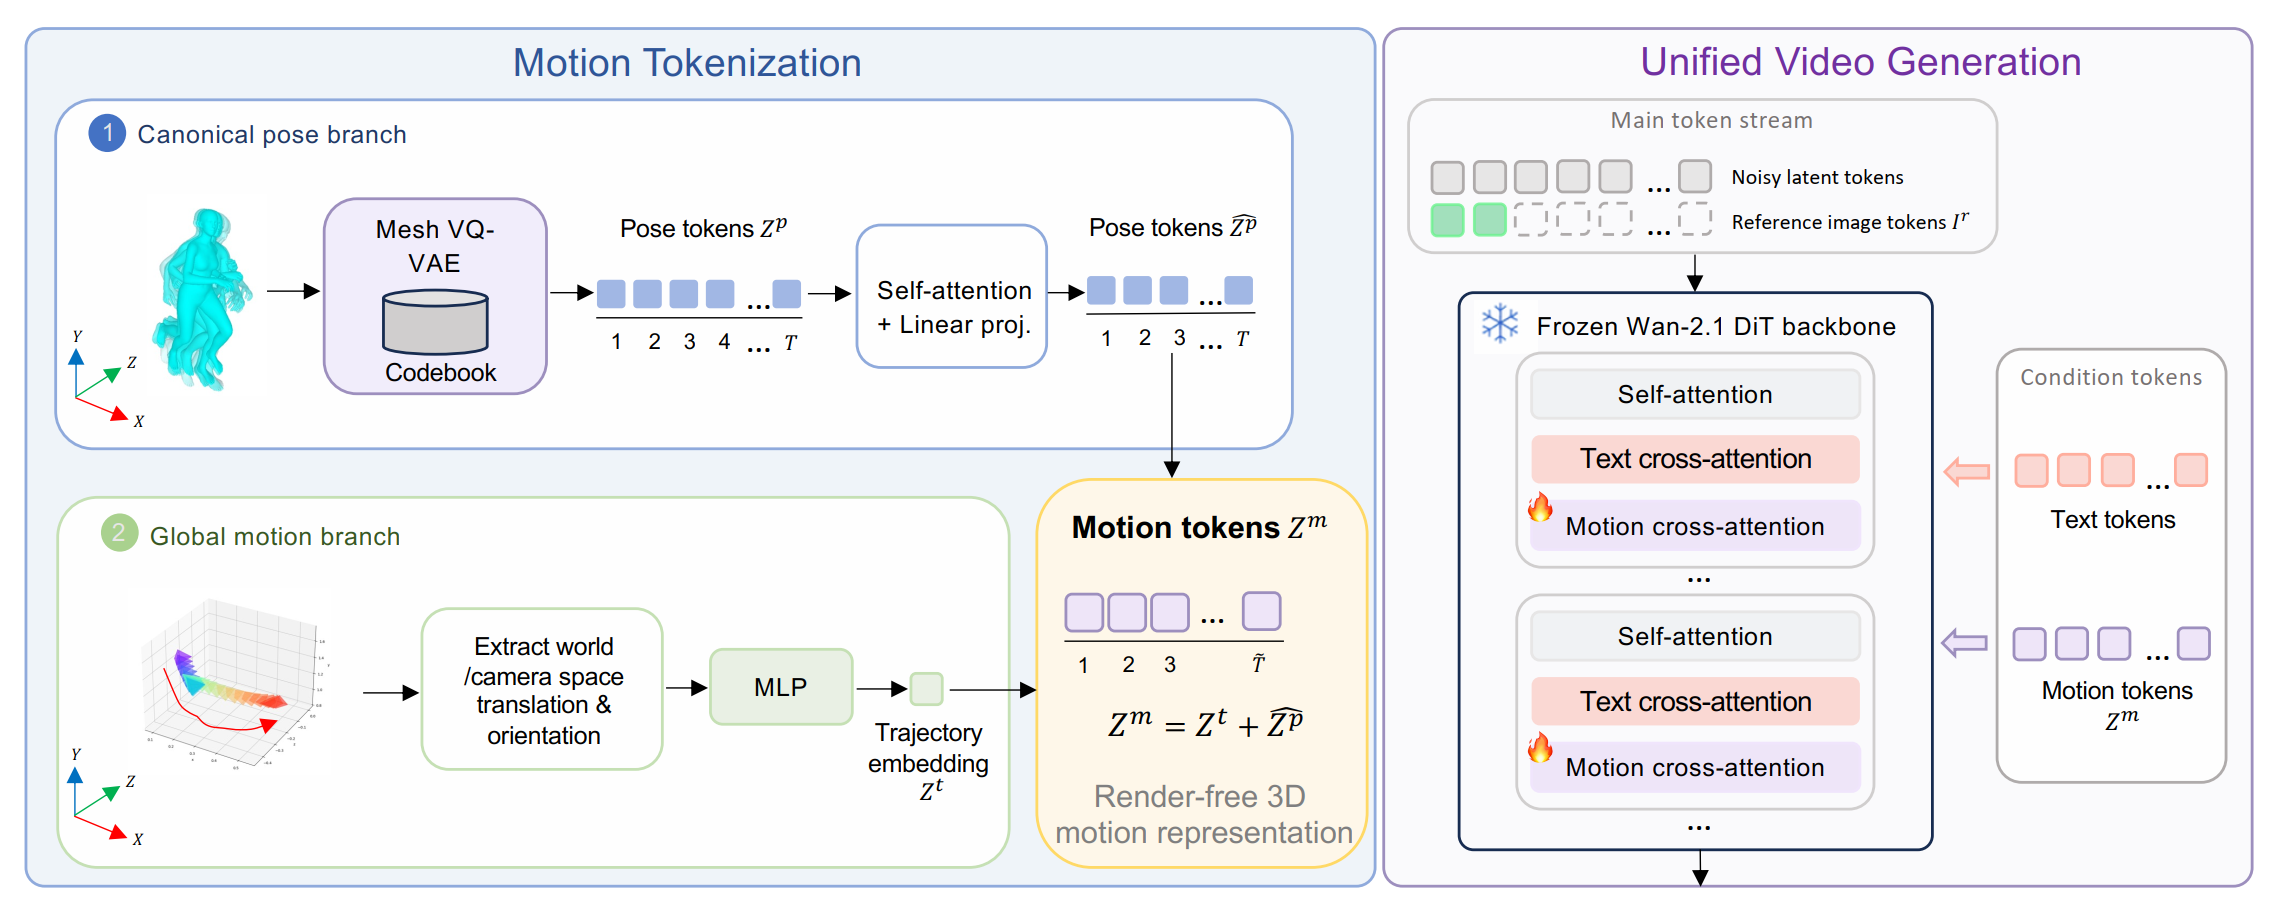
Towards 3D-Aware Video Diffusion Models: Render-Free Human Motion Control with Mesh Tokenization

Jingyun Liang, Min Wei, Shikai Li, Yizeng Han, Hangjie Yuan, Lei Sun, Weihua Chen, Fan Wang

We condition video diffusion models directly on compressed 3D human mesh tokens for render-free motion control with improved 3D structure and viewpoint awareness.

IEEE TCSVT, 2026

Aligning Vision-Language Model With Fine-Grained Semantics for Open-Vocabulary Segmentation

Yong Xien Chng*, Xuchong Qiu*, Yizeng Han, Kai Ding, Wan Ding, Gao Huang

FOV-Seg aligns pixel-level visual features with word-level semantics through masked text reconstruction and text-guided visual encoding.

More publications
distillation
Technical report, 2025

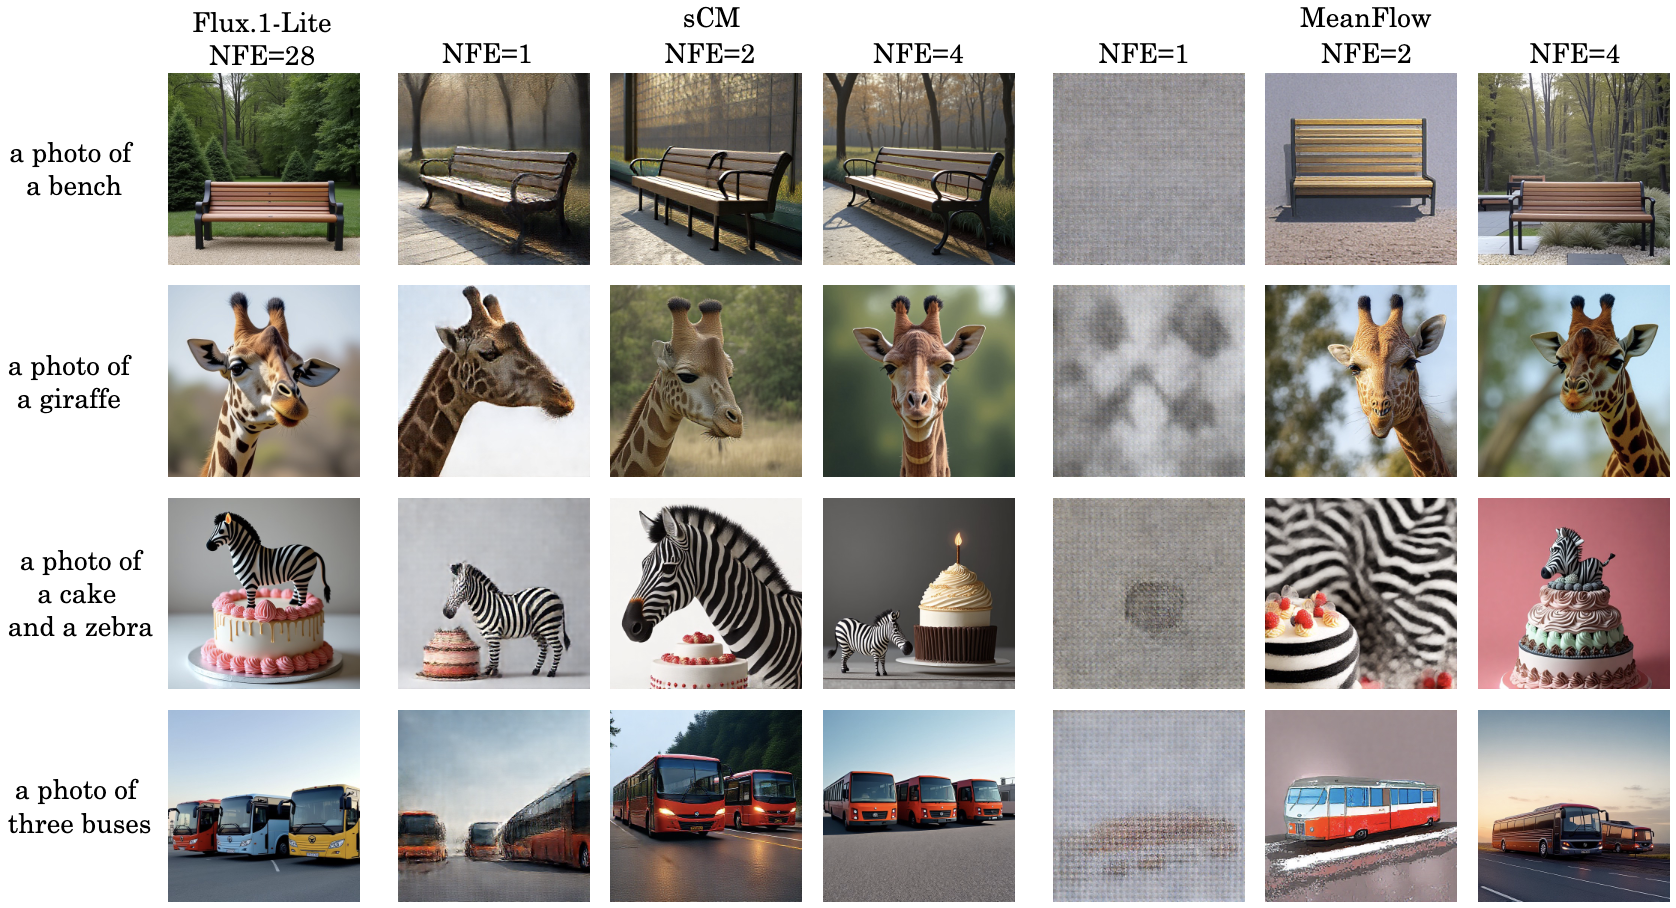
Few-Step Distillation for Text-to-Image Generation: A Practical Guide

Yifan Pu*, Yizeng Han*, Zhiwei Tang*, Jiasheng Tang, Fan Wang, Bohan Zhuang, Gao Huang
Inferix
arXiv preprint, 2025

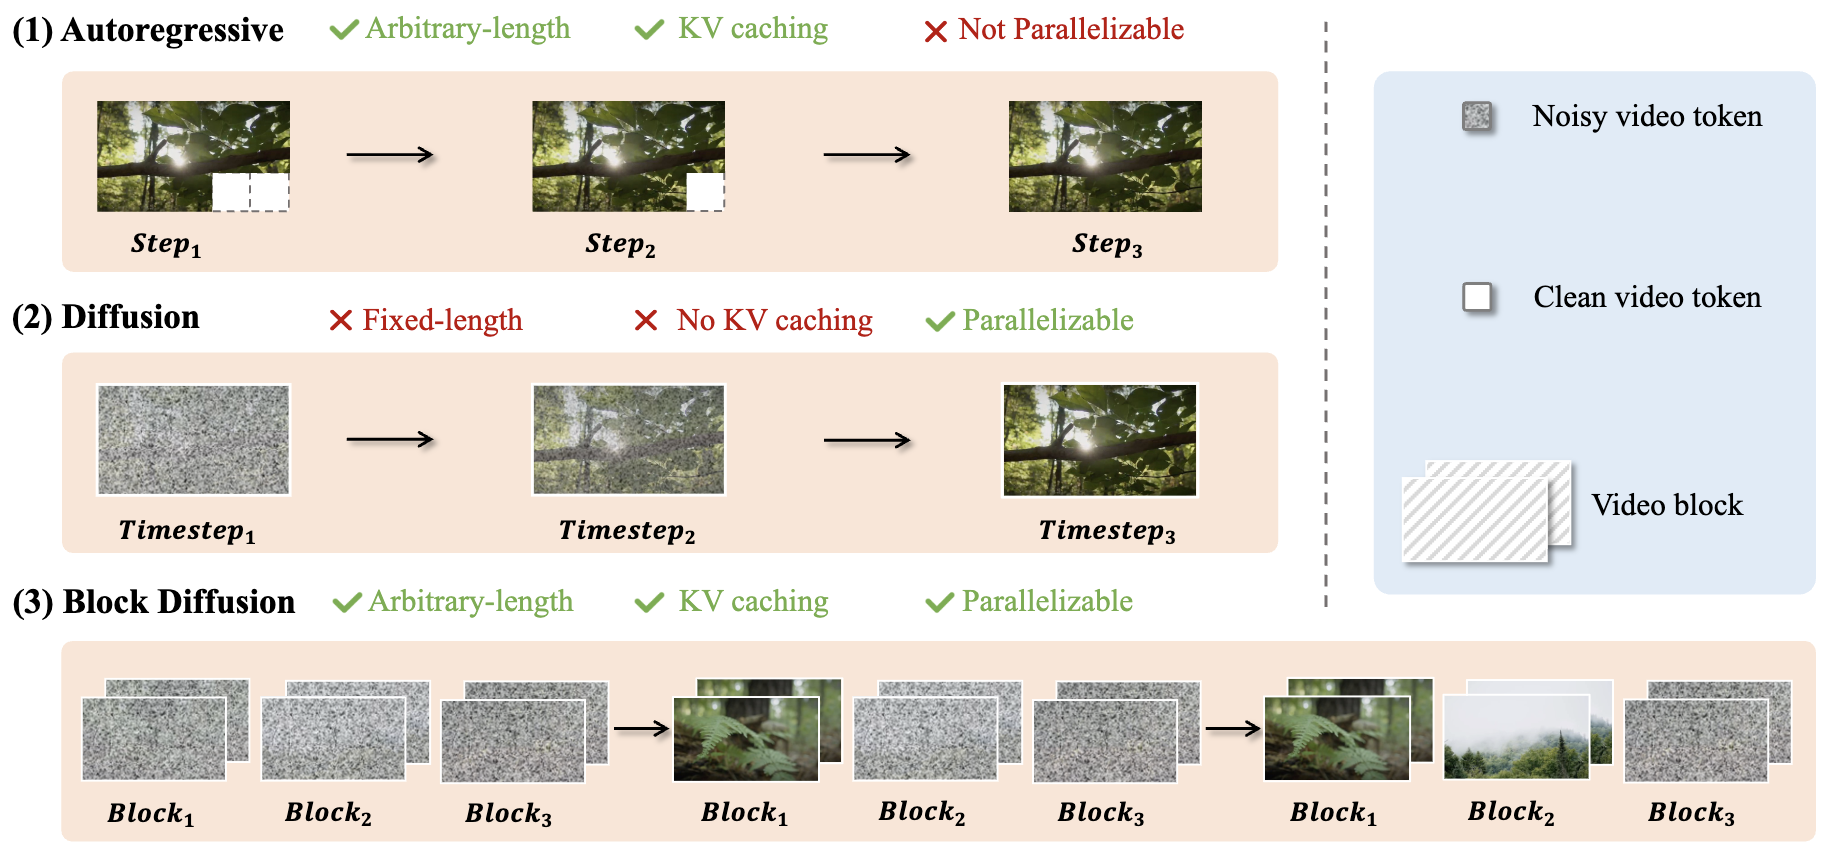
Inferix: A Block-Diffusion based Next-Generation Inference Engine for World Simulation

Inferix Team: Tianyu Feng, Yizeng Han, Jiahao He, Yuanyu He, Xi Lin, Teng Liu, Hanfeng Lu, Jiasheng Tang, Wei Wang, Zhiyuan Wang, Jichao Wu, Mingyang Yang, Yinghao Yu, Zeyu Zhang, Bohan Zhuang
AdaptiveNN
Nature Machine Intelligence, 2025

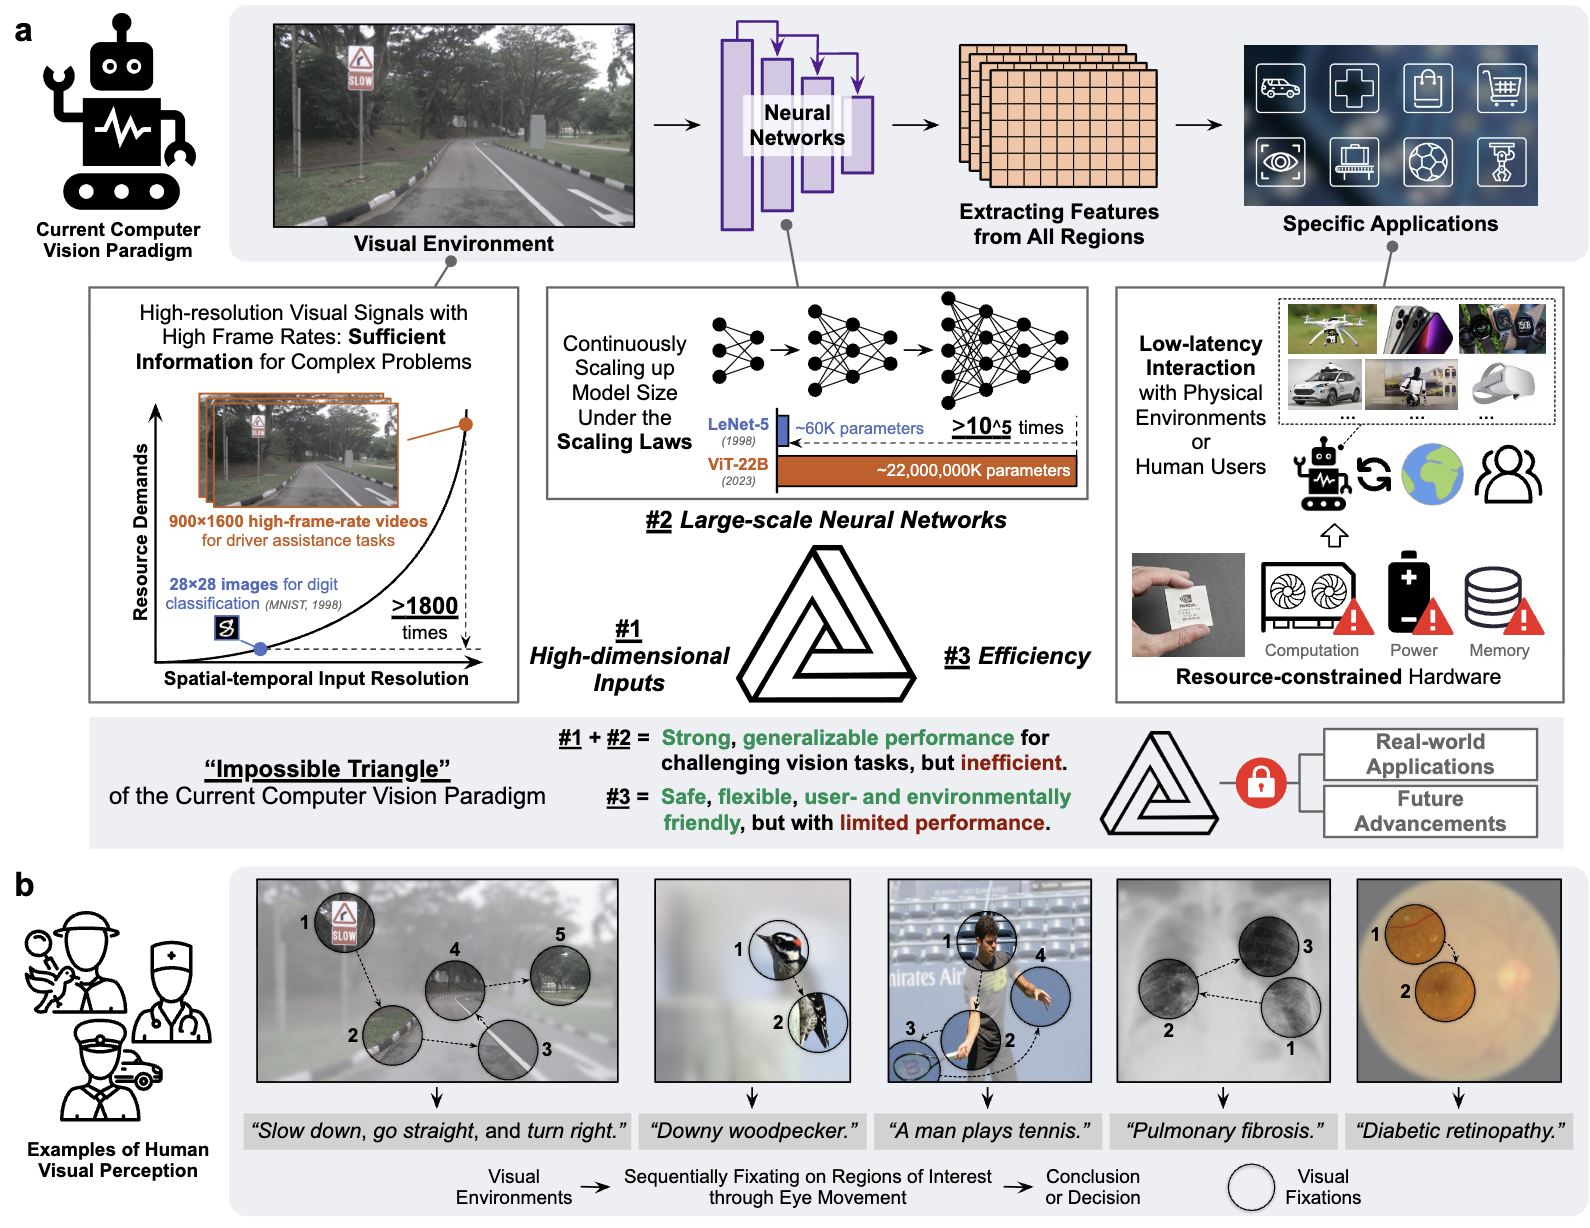
Emulating Human-like Adaptive Vision for Efficient and Flexible Machine Visual Perception

Yulin Wang, Yang Yue, Yang Yue, Huanqian Wang, Haojun Jiang, Yizeng Han, Zanlin Ni, Yifan Pu, Minglei Shi, Rui Lu, Qisen Yang, Andrew Zhao, Zhuofan Xia, Shiji Song, Gao Huang
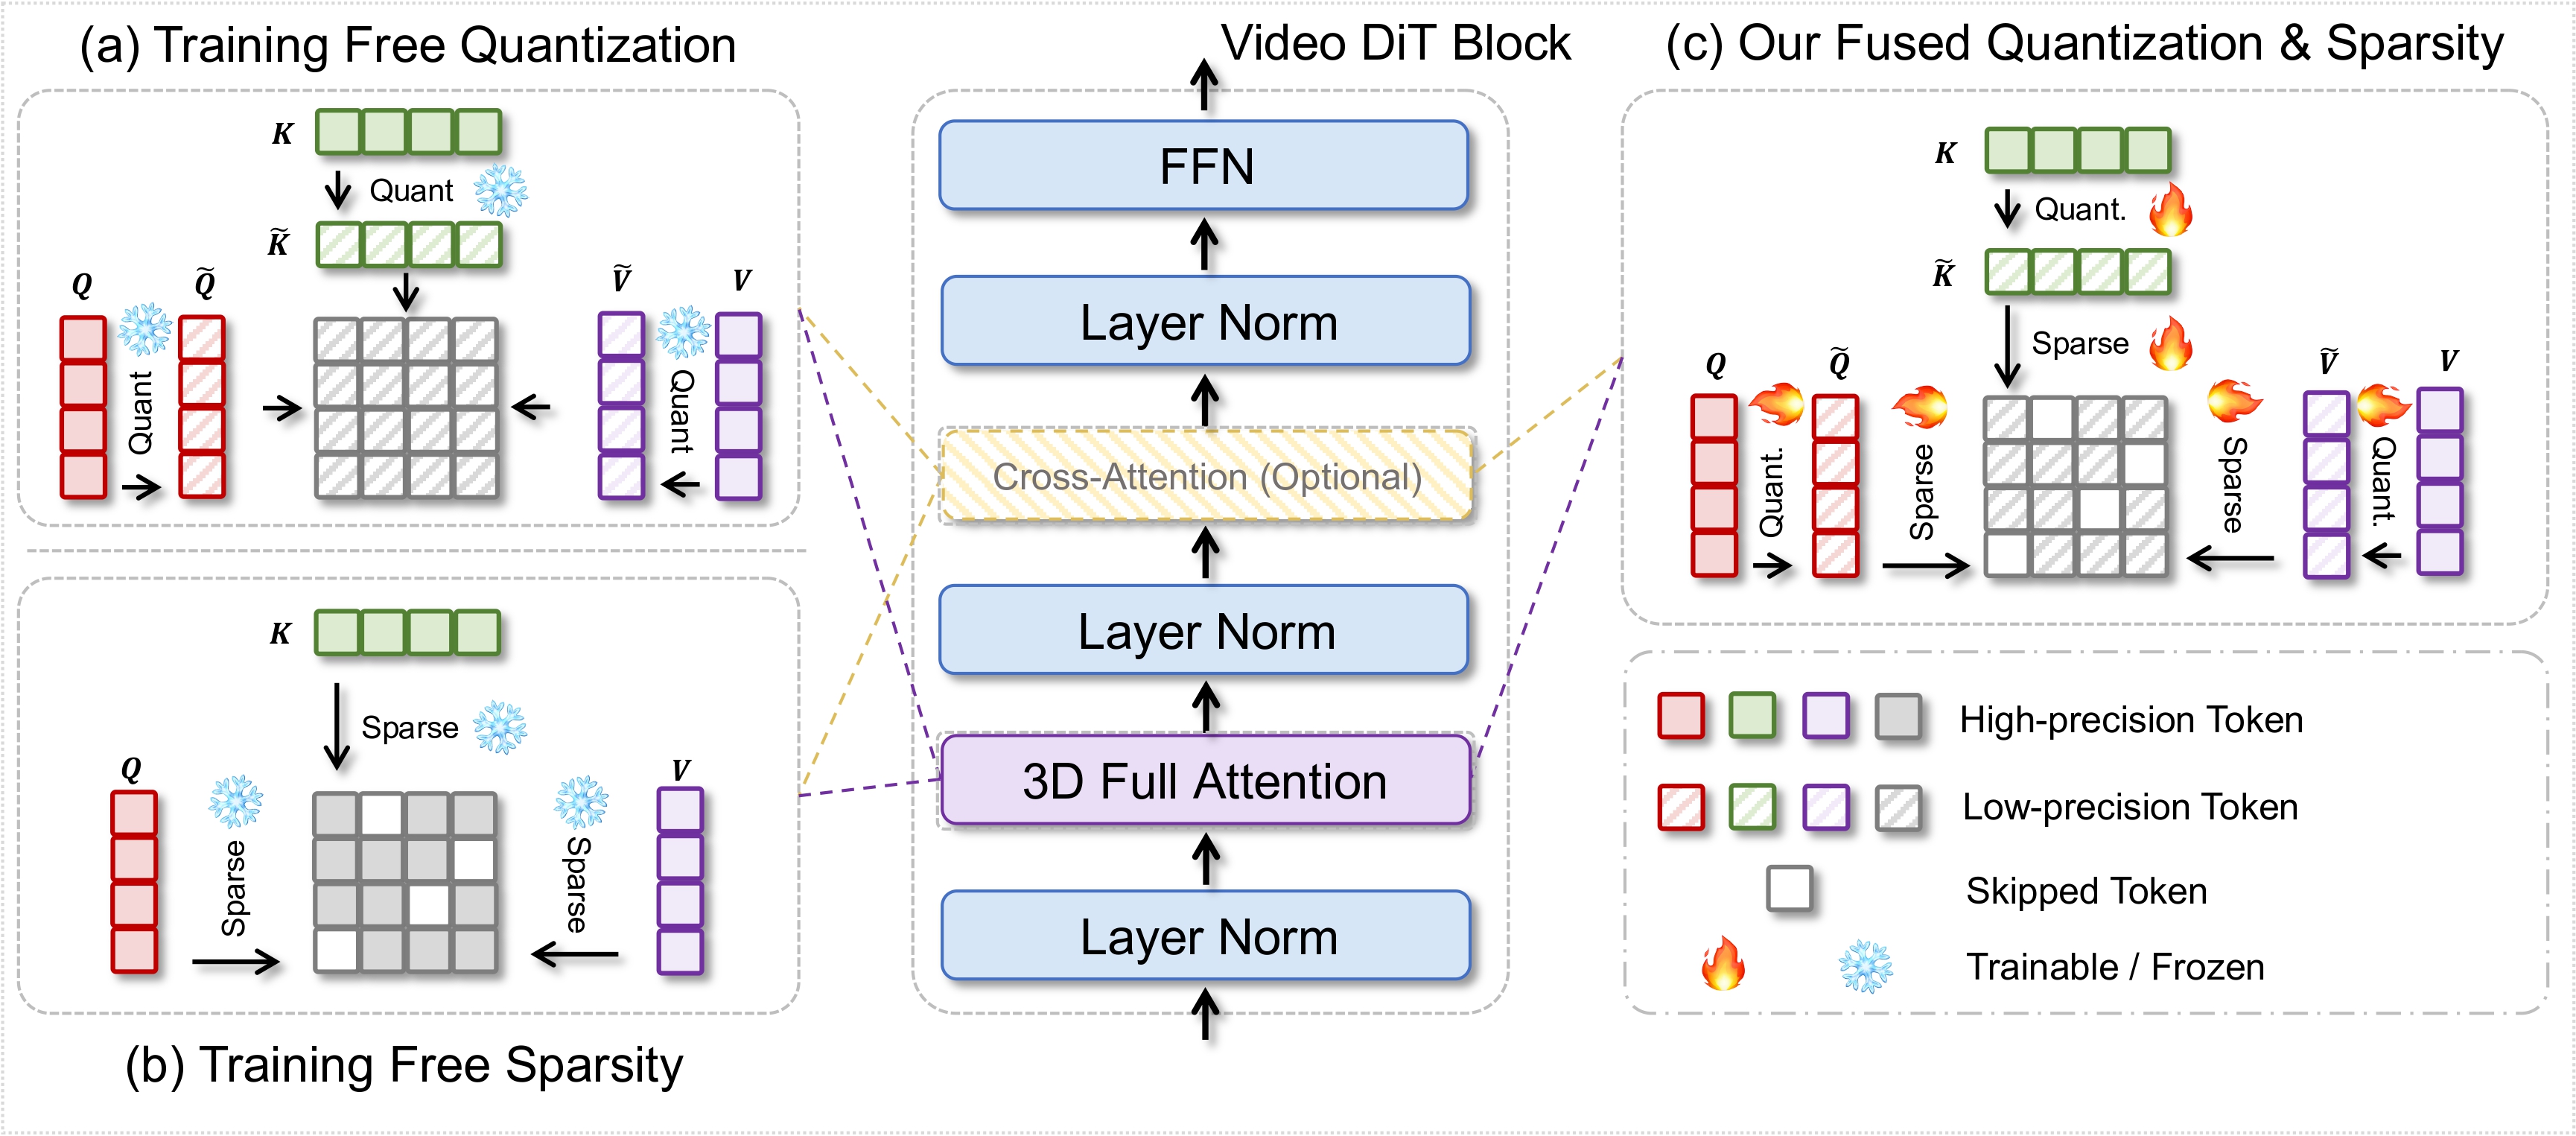
FPSAttention
NeurIPS (Highlight), 2025

FPSAttention: Training-Aware FP8 and Sparsity Co-Design for Fast Video Diffusion

Akide Liu, Zeyu Zhang, Zhexin Li, Xuehai Bai, Yizeng Han, Jiasheng Tang, Yuanjie Xing, Jichao Wu, Mingyang Yang, Weihua Chen, Jiahao He, Yuanyu He, Fan Wang, Gholamreza Haffari, Bohan Zhuang
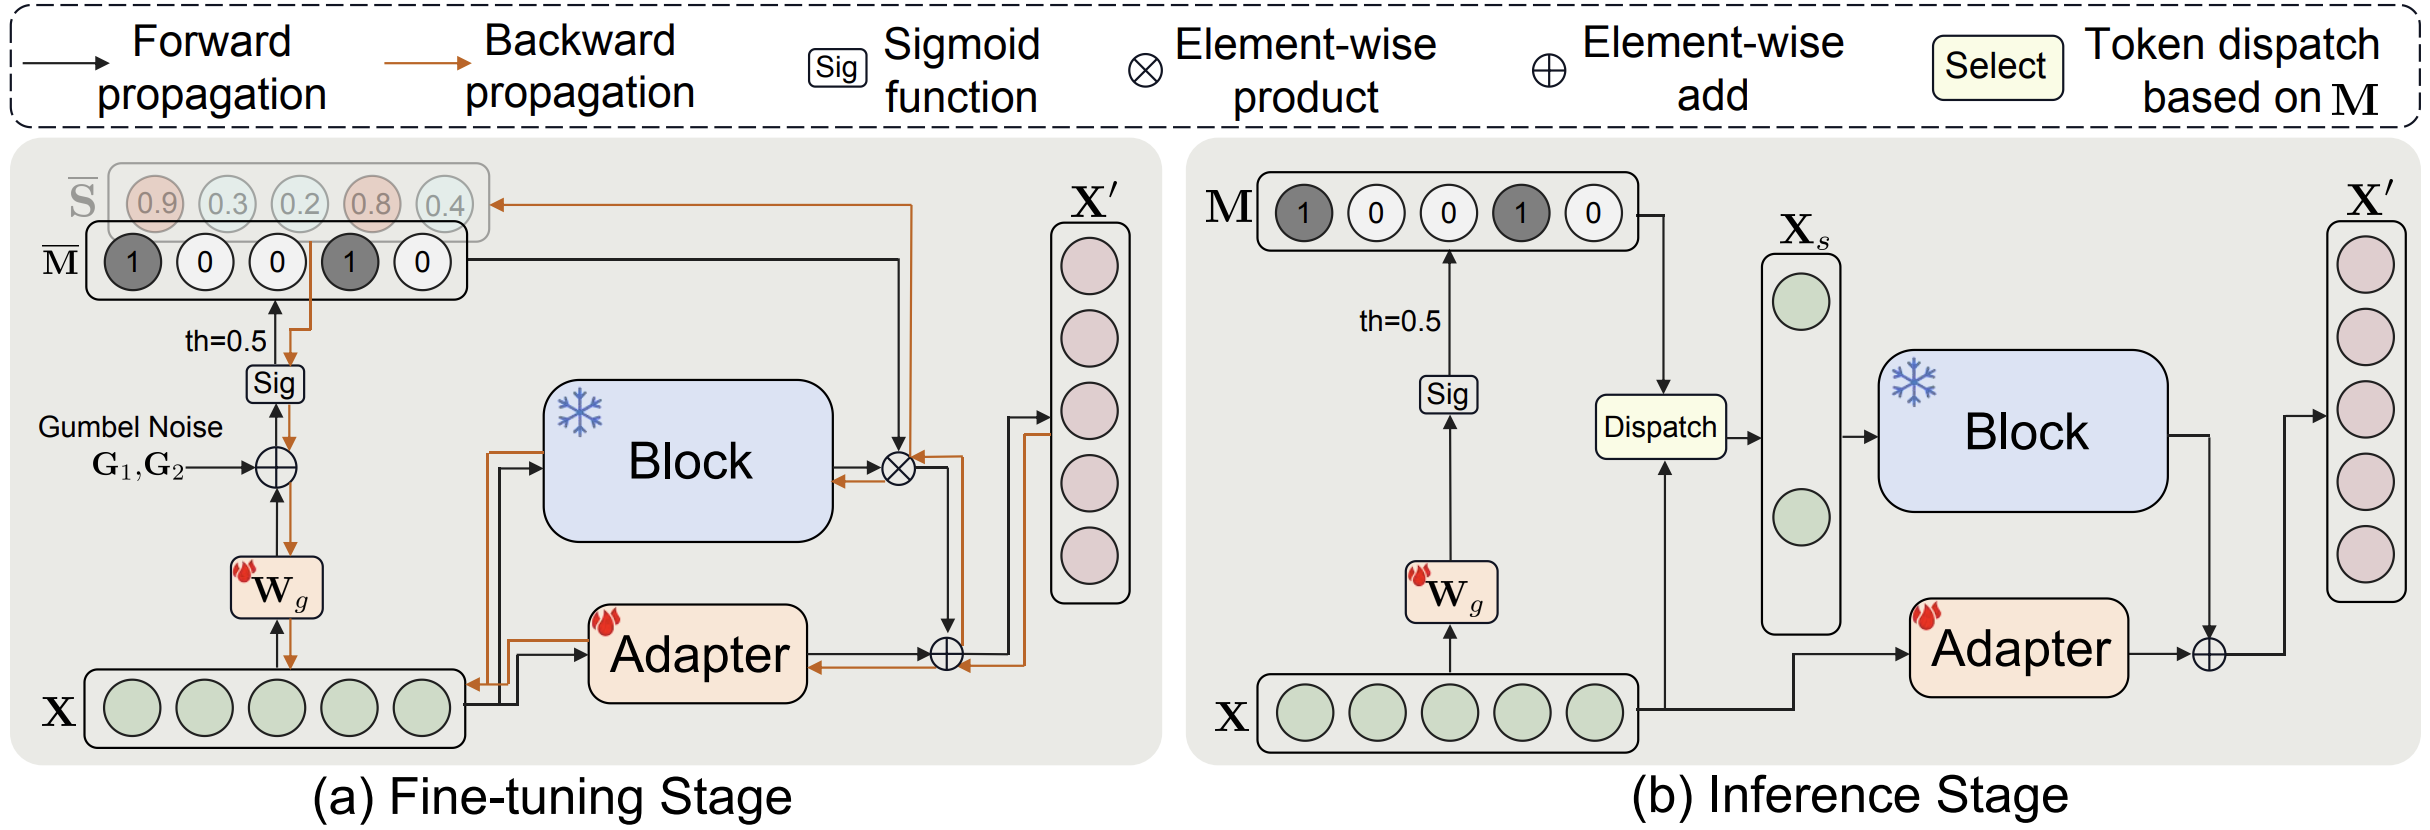
DyT
NeurIPS, 2024

Dynamic Tuning Towards Parameter and Inference Efficiency for ViT Adaptation

Wangbo Zhao, Jiasheng Tang, Yizeng Han, Yibing Song, Kai Wang, Gao Huang, Fan Wang, Yang You
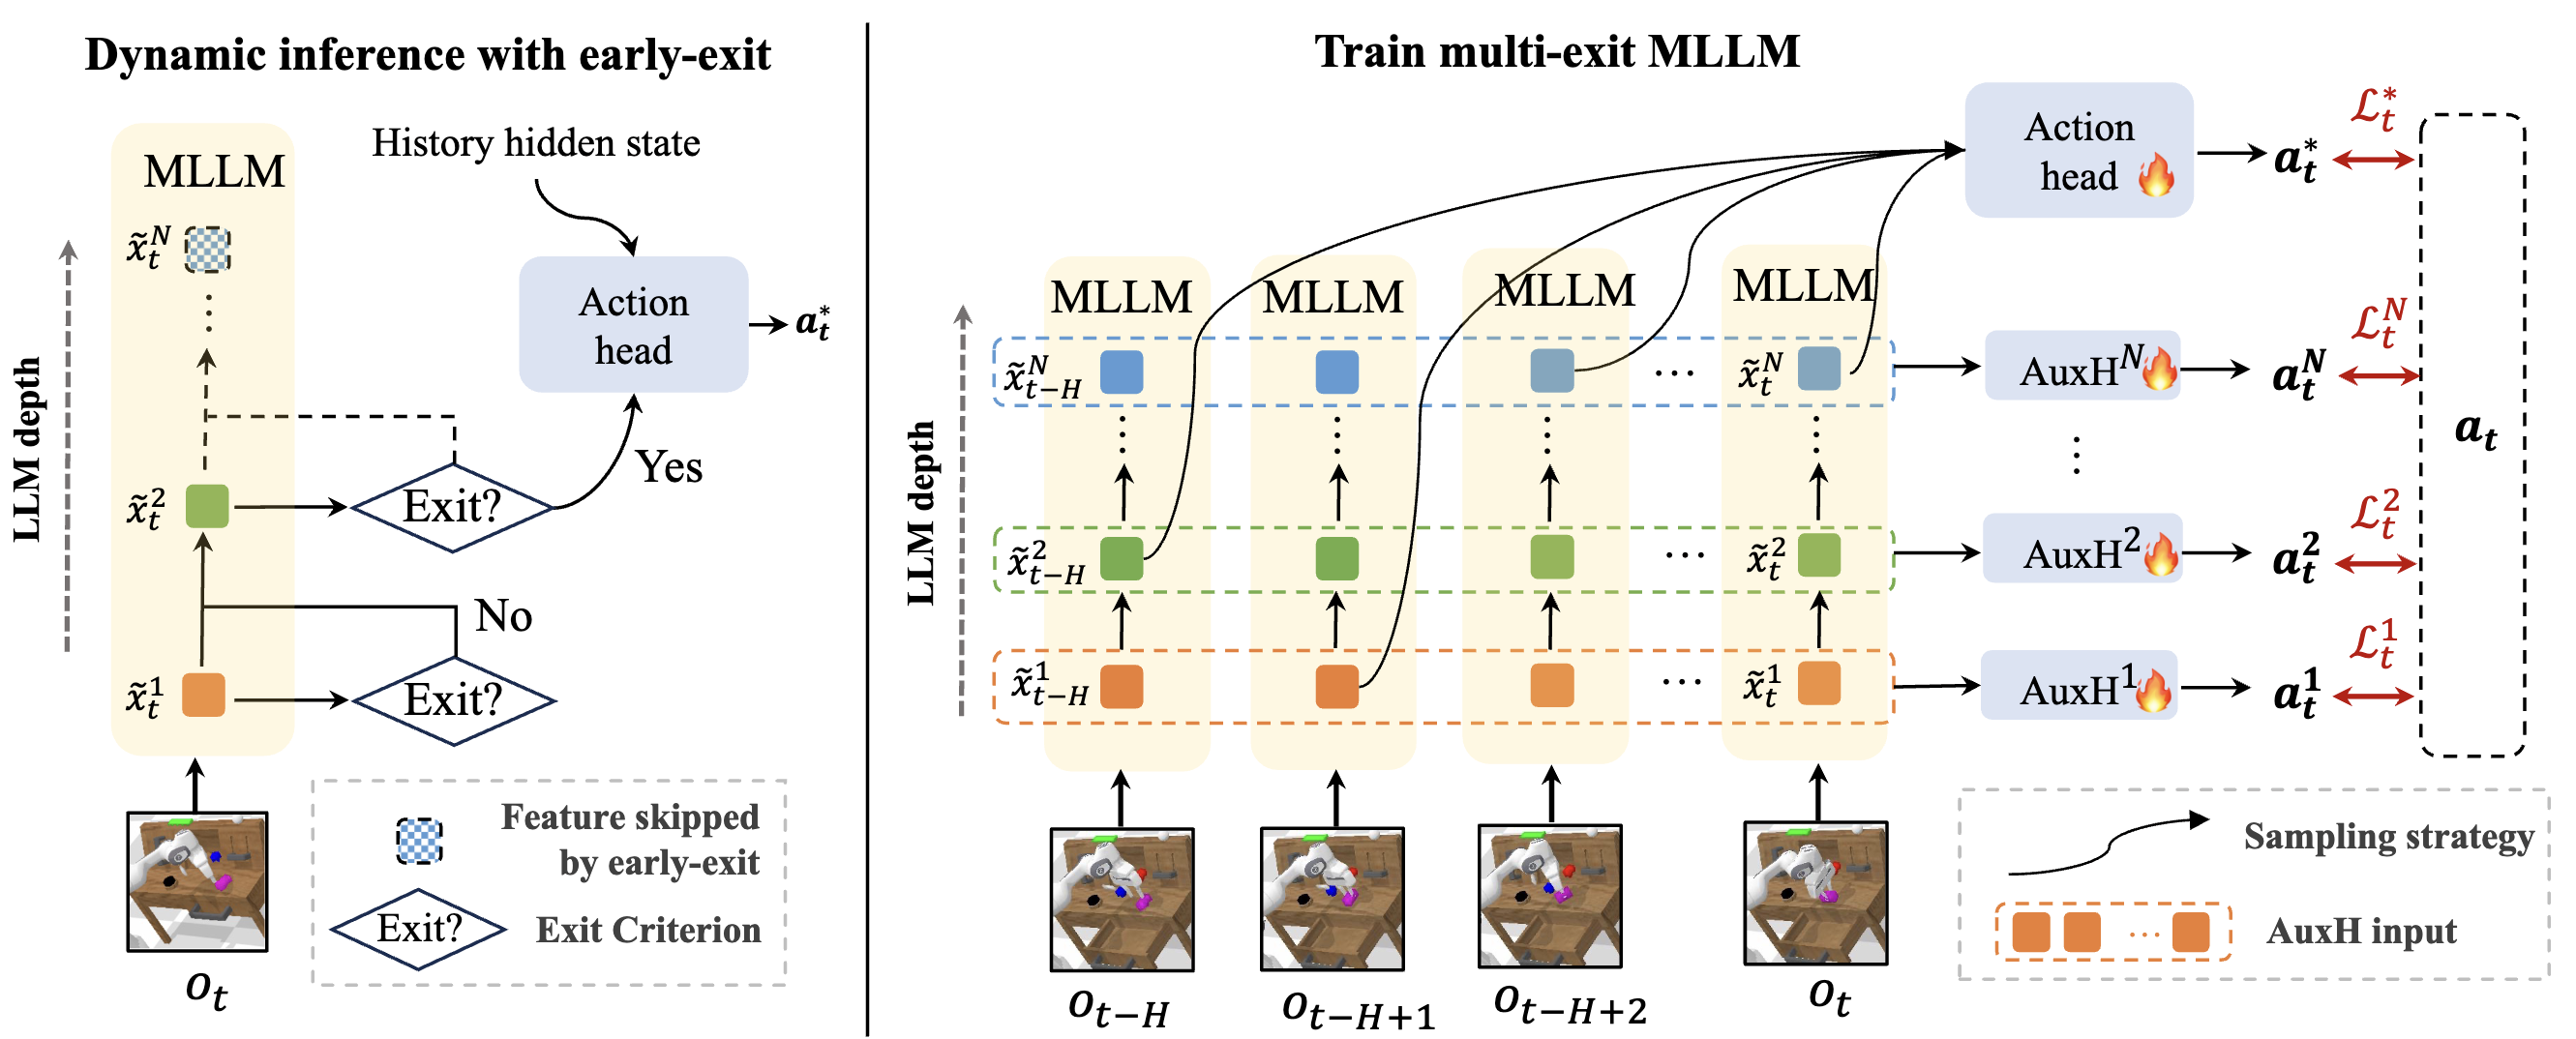
Deer
NeurIPS, 2024

DeeR-VLA: Dynamic Inference of Multimodal Large Language Models for Efficient Robot Execution

Yang Yue, Yulin Wang, Bingyi Kang, Yizeng Han, Shenzhi Wang, Shiji Song, Jiashi Feng, Gao Huang

Earlier highlights

Survey
IEEE TPAMI, 2021

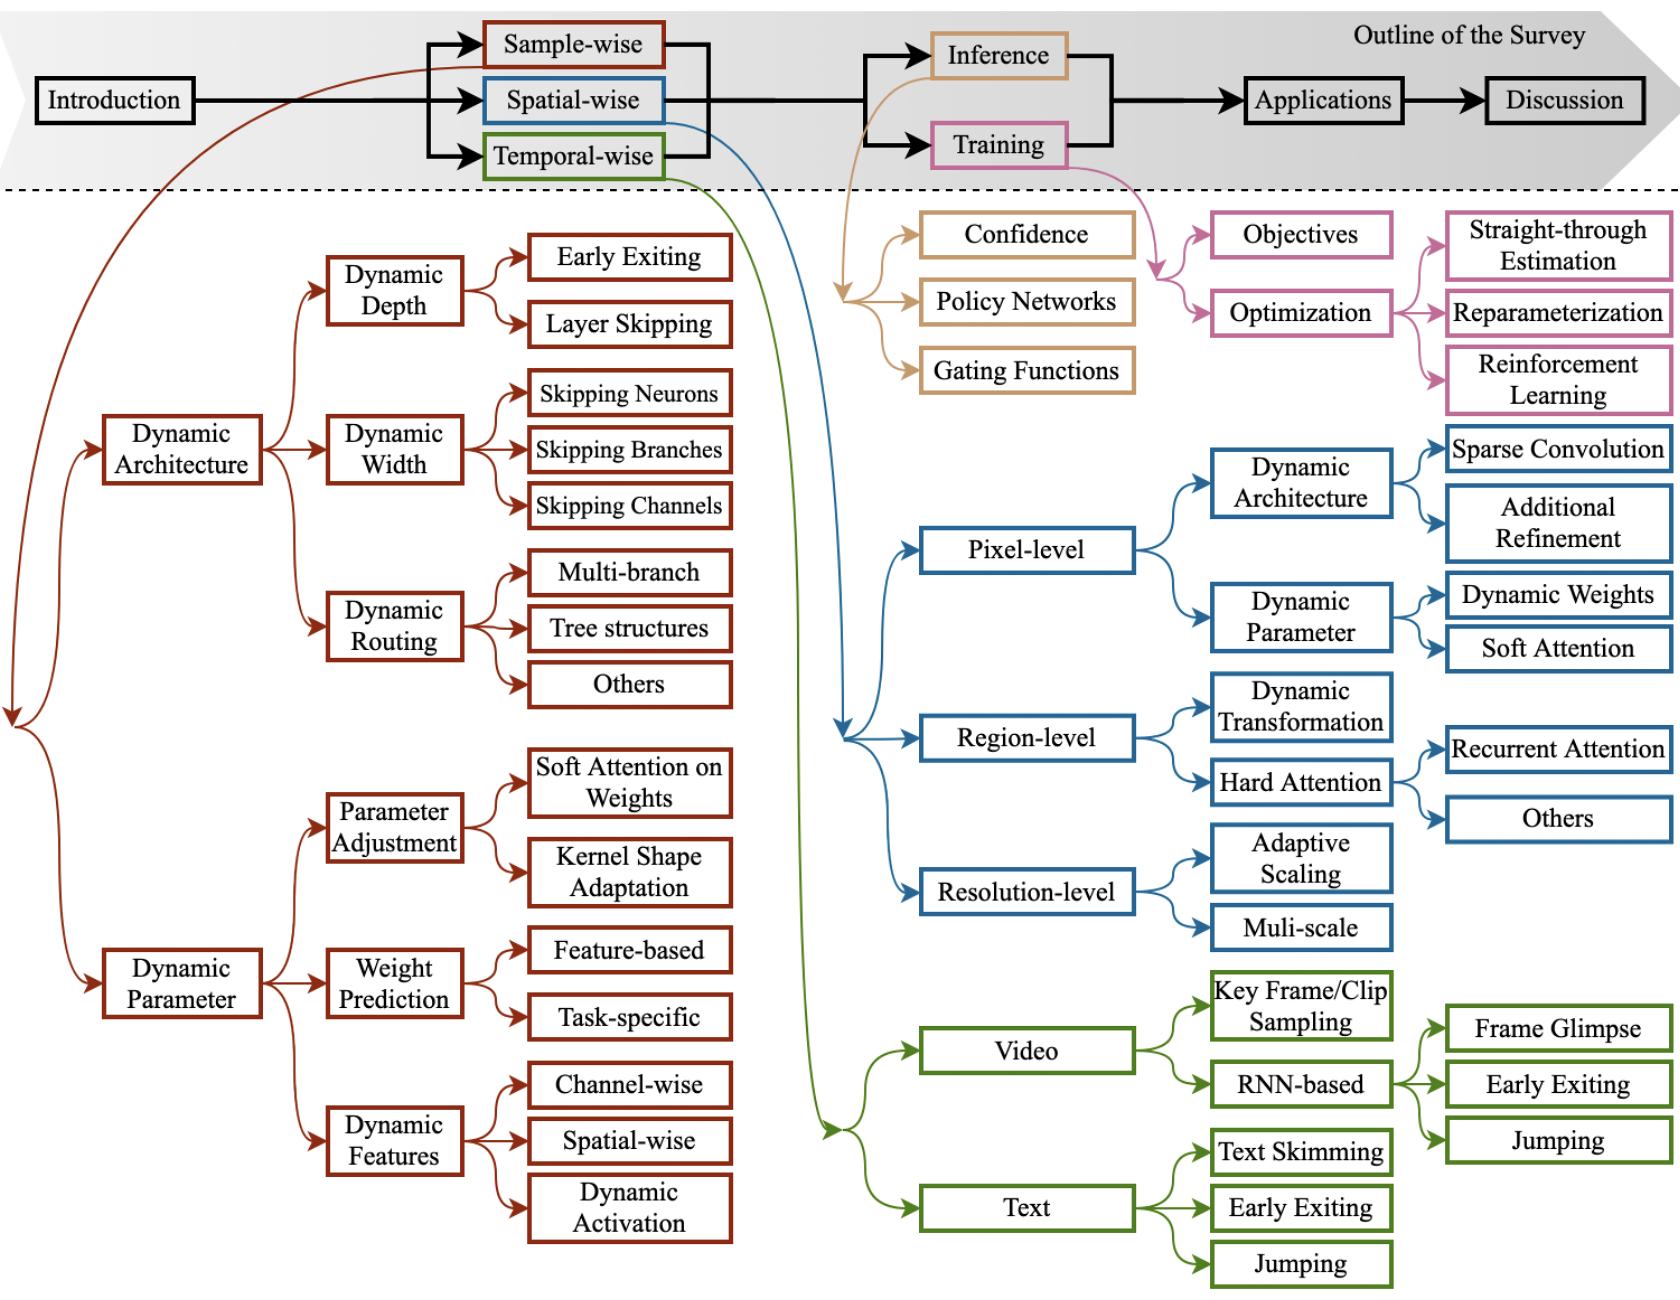
Dynamic Neural Networks: A Survey

Yizeng Han*, Gao Huang*, Shiji Song, Le Yang, Honghui Wang, Yulin Wang

In this survey, we comprehensively review the rapidly developing area, dynamic neural networks.

LAUDNet
IEEE TPAMI, 2024

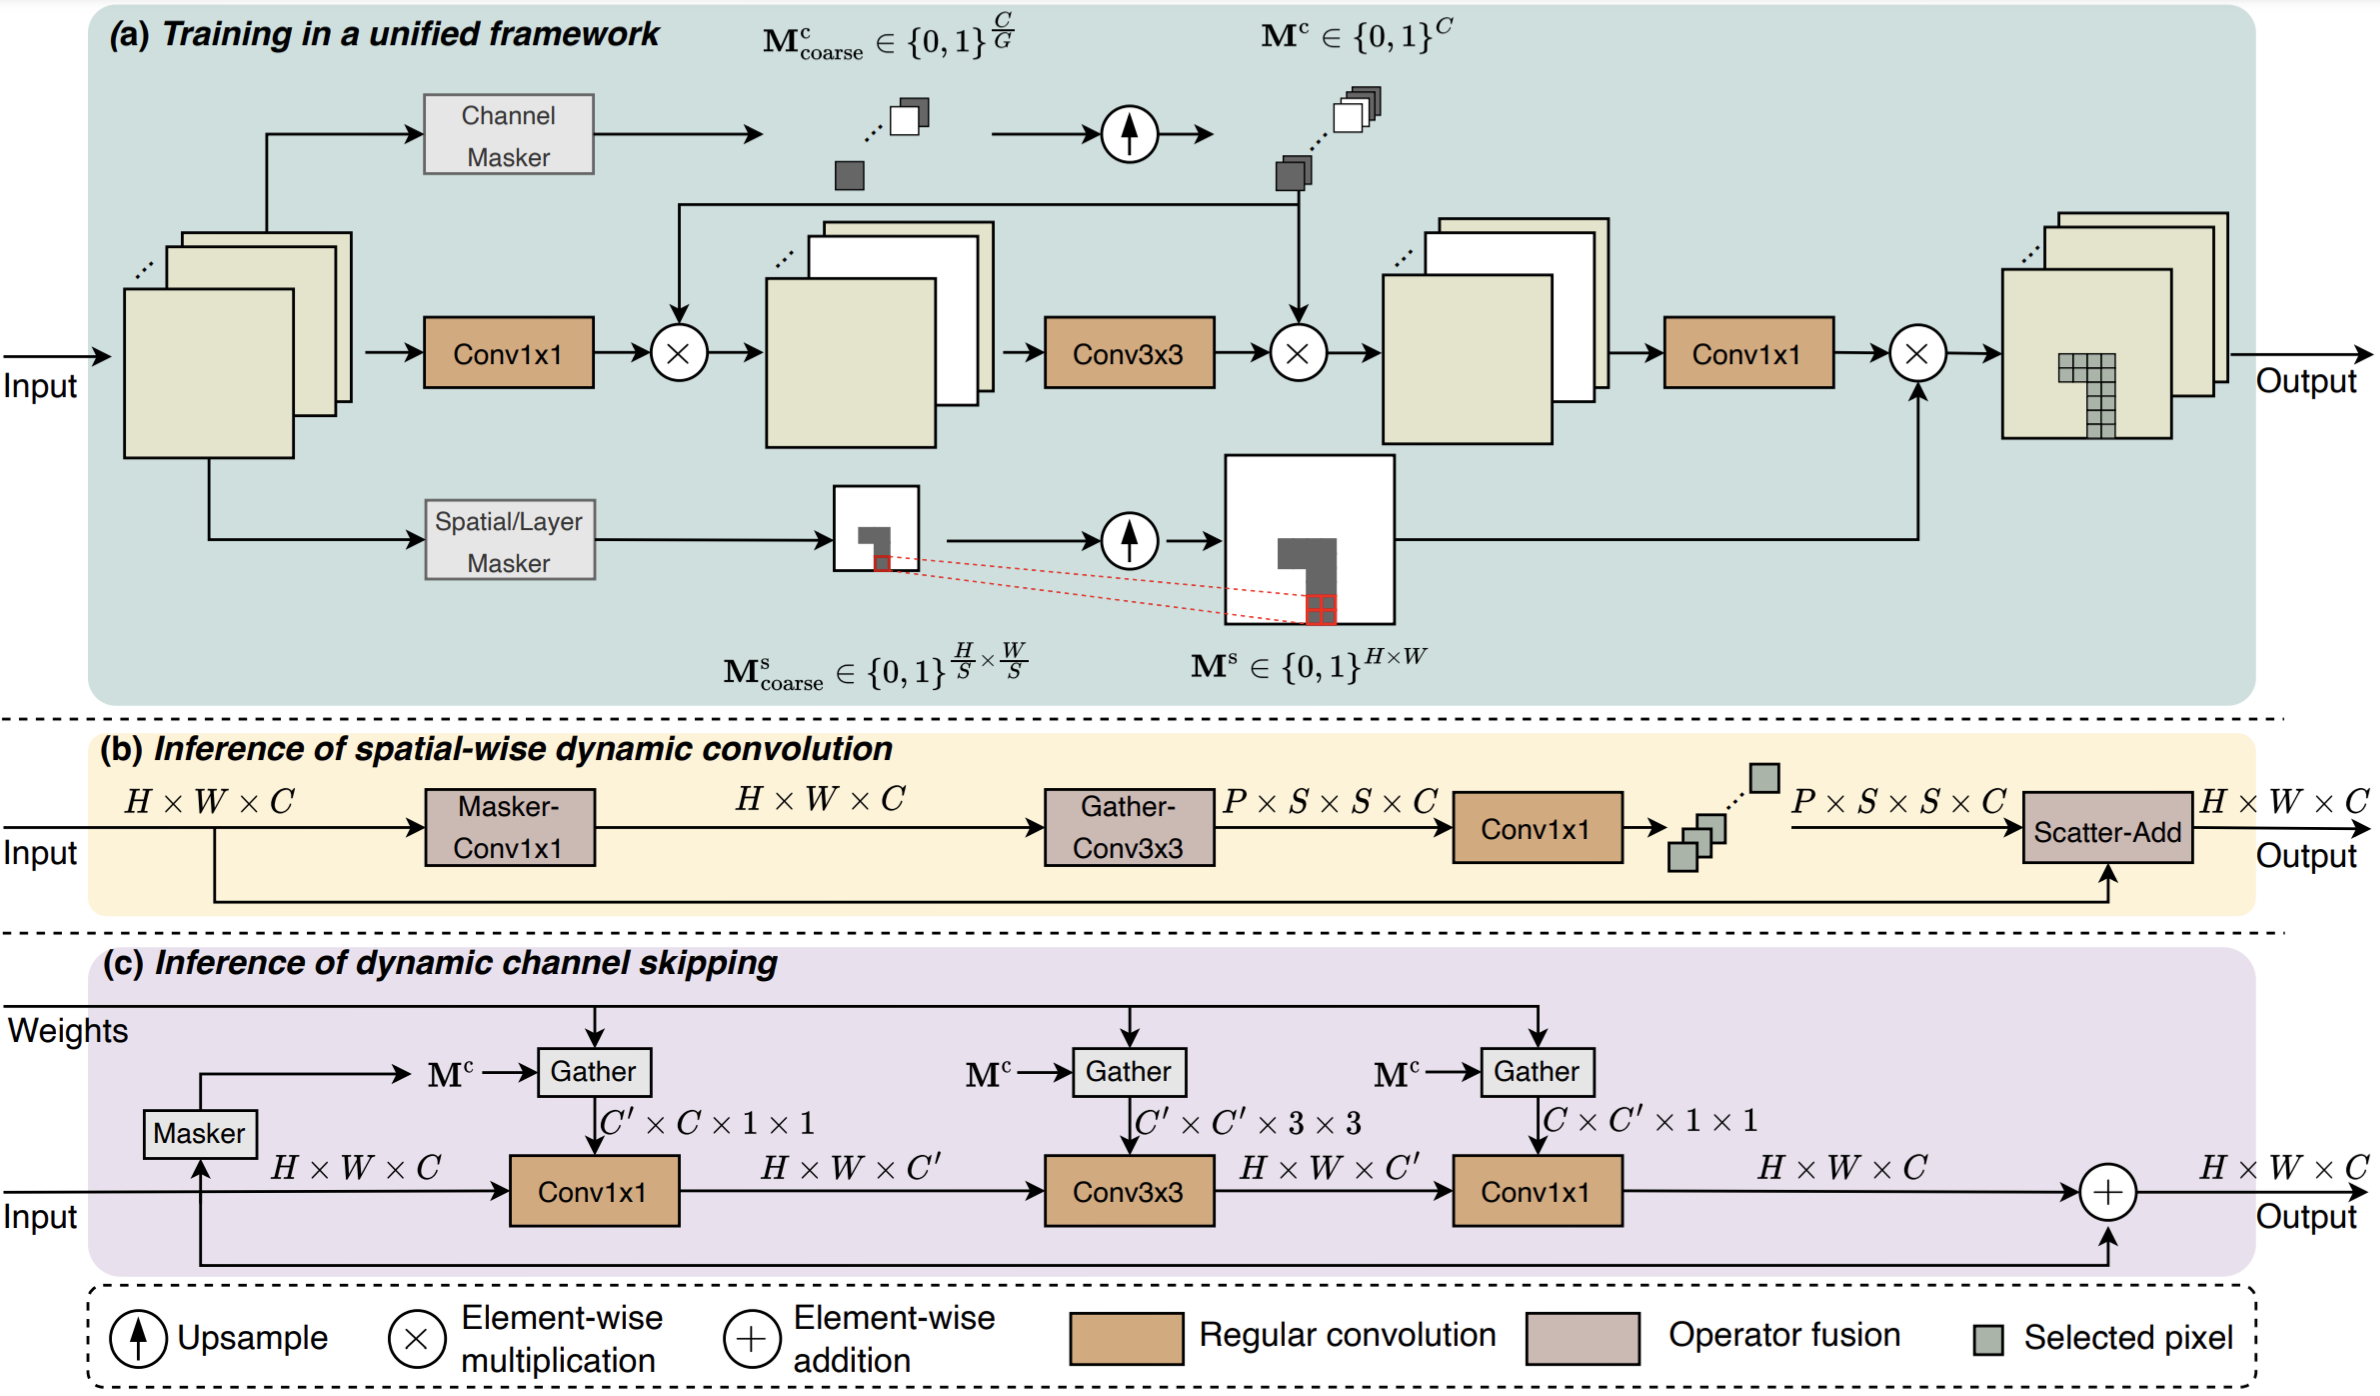
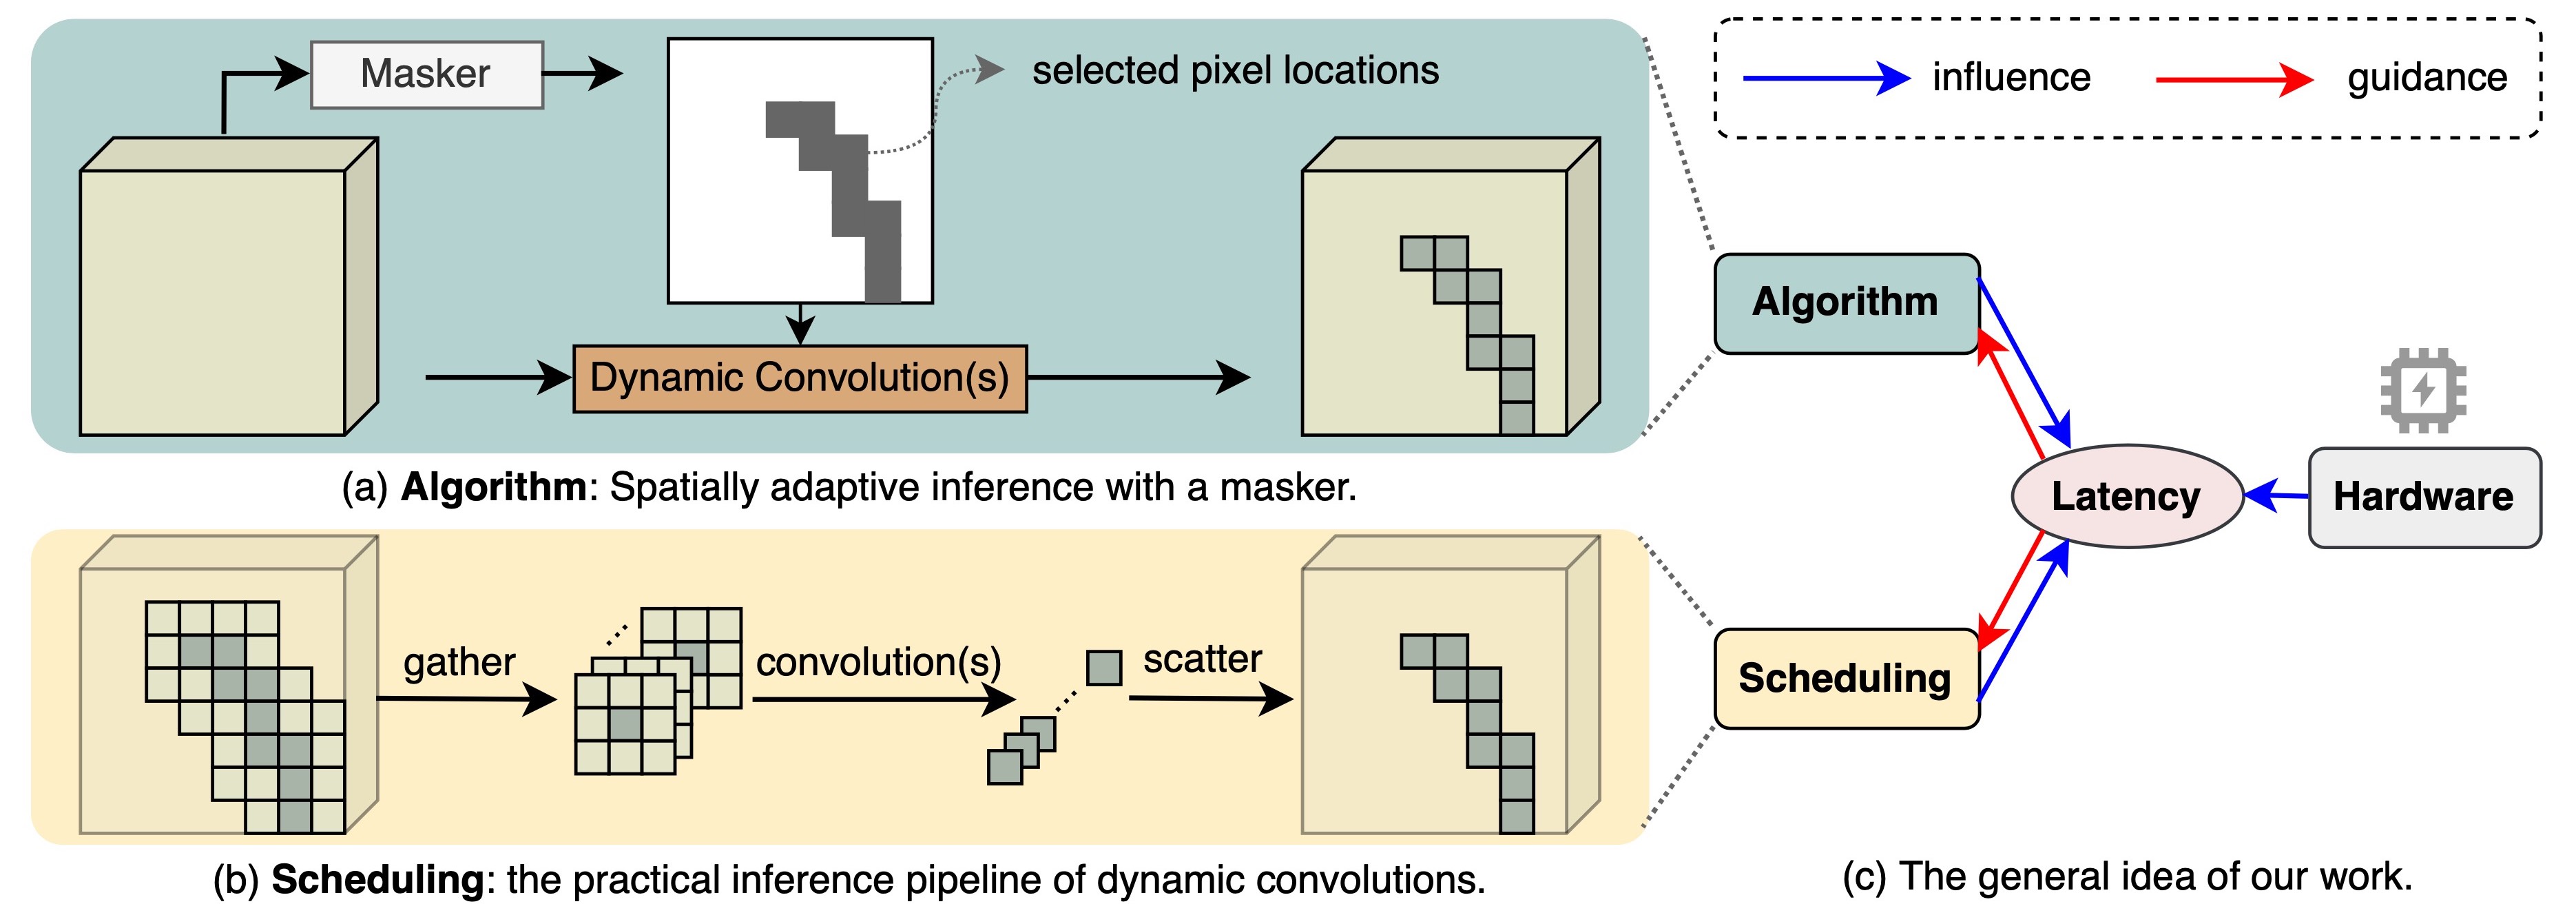
Latency-aware Unified Dynamic Networks for Efficient Image Recognition

Yizeng Han*, Zeyu Liu*, Zhihang Yuan*, Yifan Pu, Chaofei Wang, Shiji Song, Gao Huang
DyDiT
ICLR, 2025

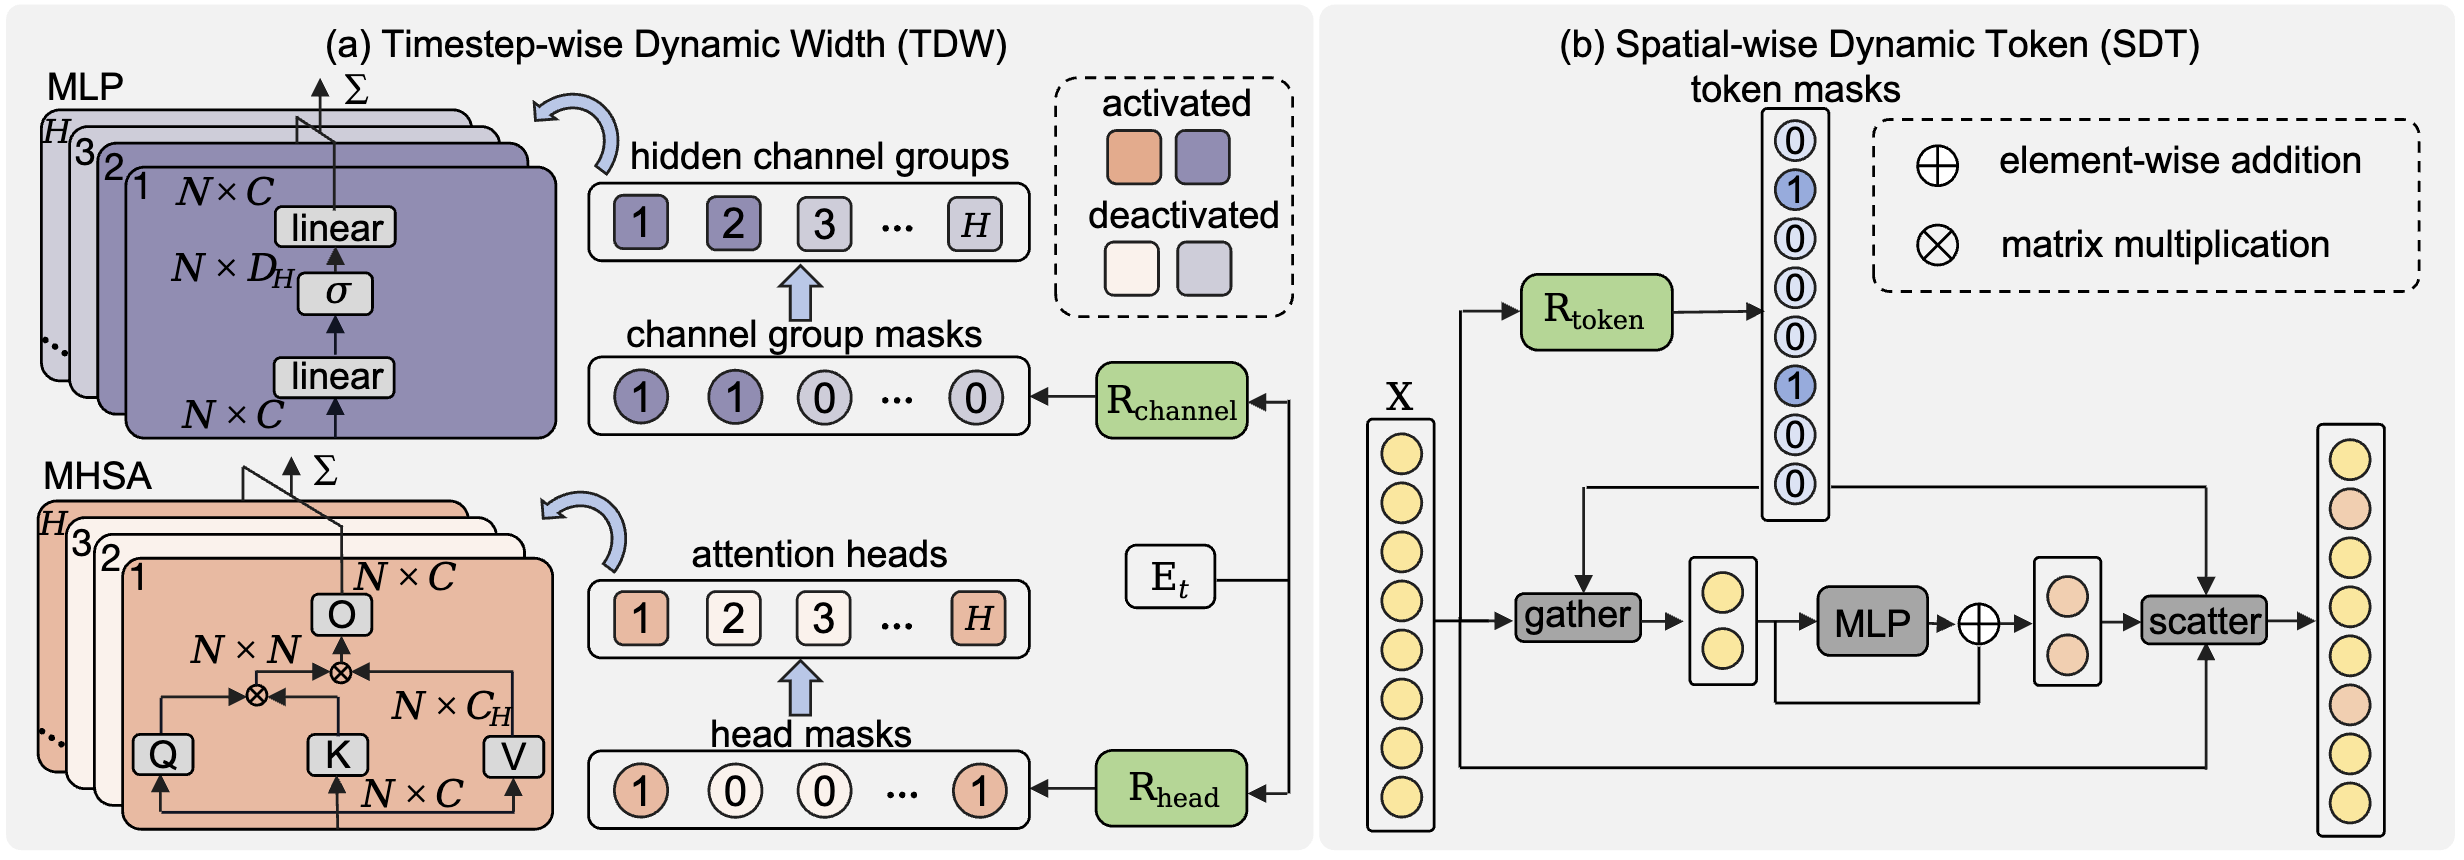
Dynamic Diffusion Transformer

Wangbo Zhao, Yizeng Han, Jiasheng Tang, Kai Wang, Yibing Song, Gao Huang, Fan Wang, Yang You
Dyn_Perceiver
ICCV, 2023

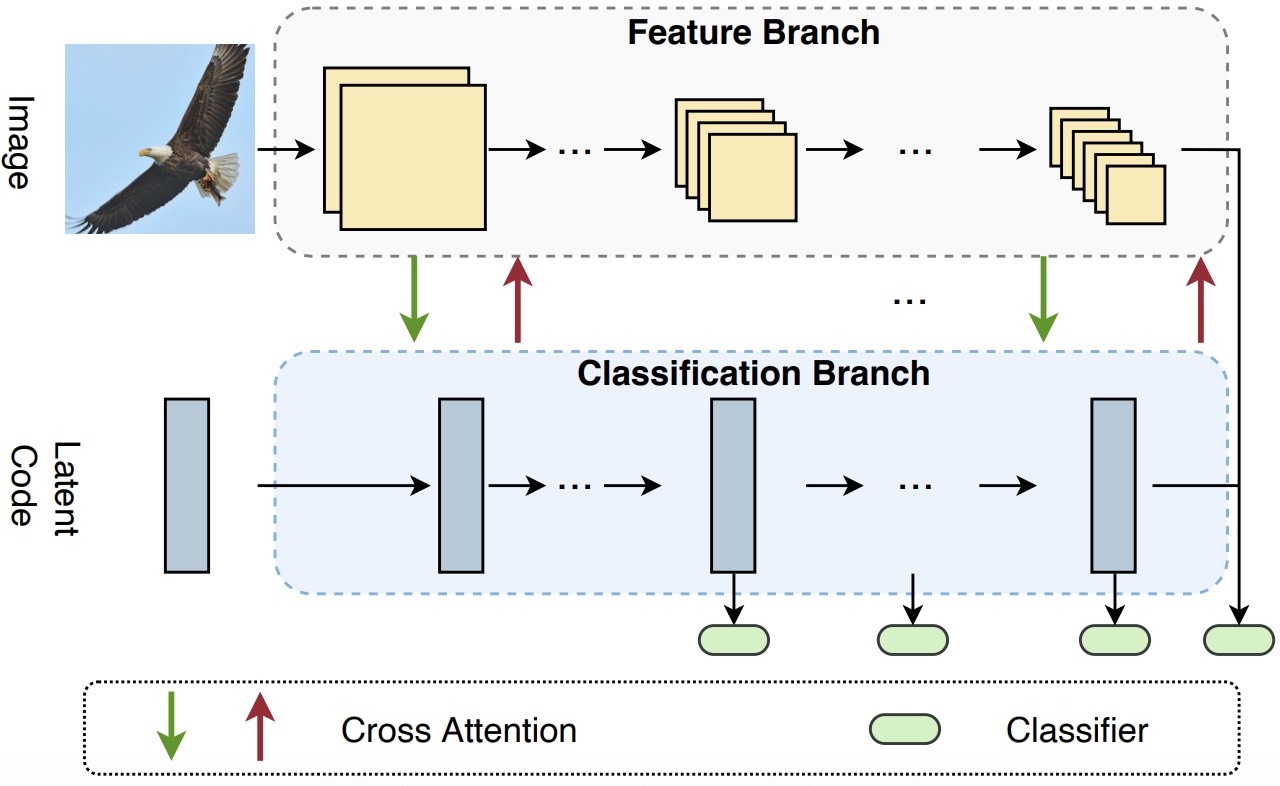
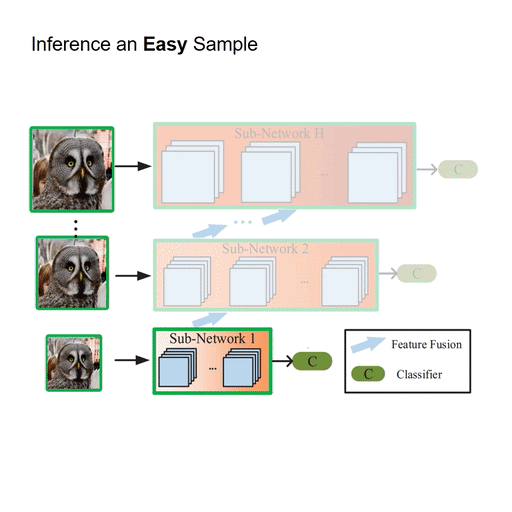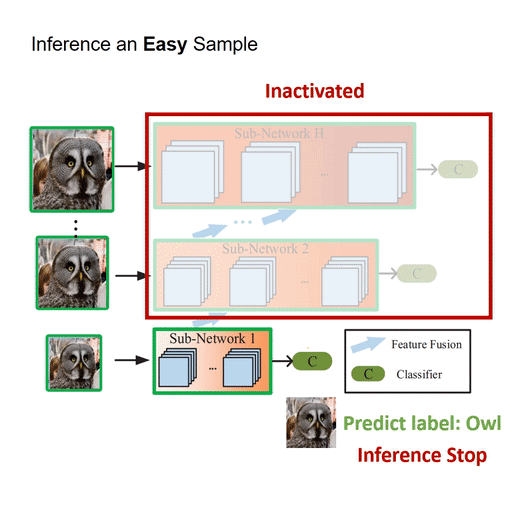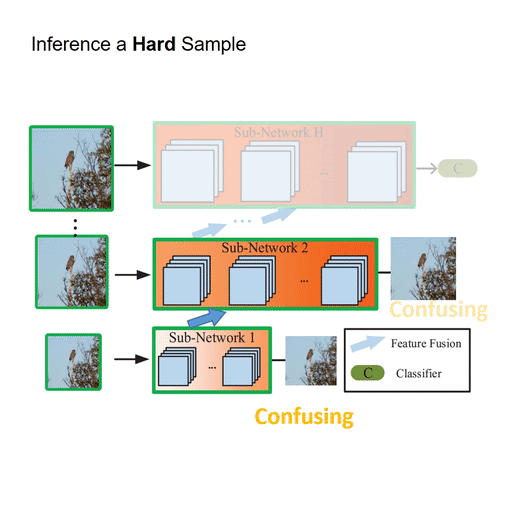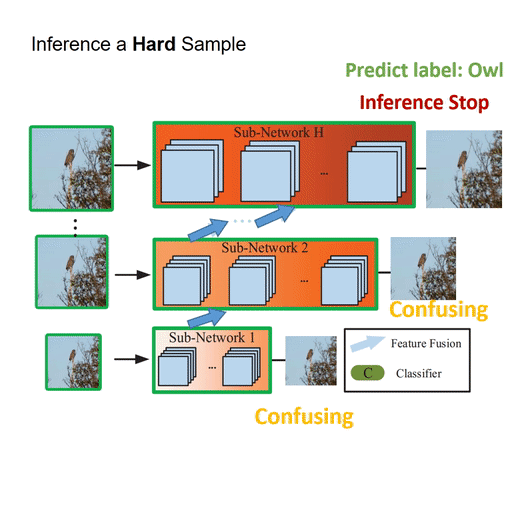
Dynamic Perceiver for Efficient Visual Recognition

Yizeng Han*, Dongchen Han*, Zeyu Liu, Yulin Wang, Xuran Pan, Yifan Pu, Chao Deng, Junlan Feng, Shiji Song, Gao Huang
L2W-DEN
ECCV, 2022

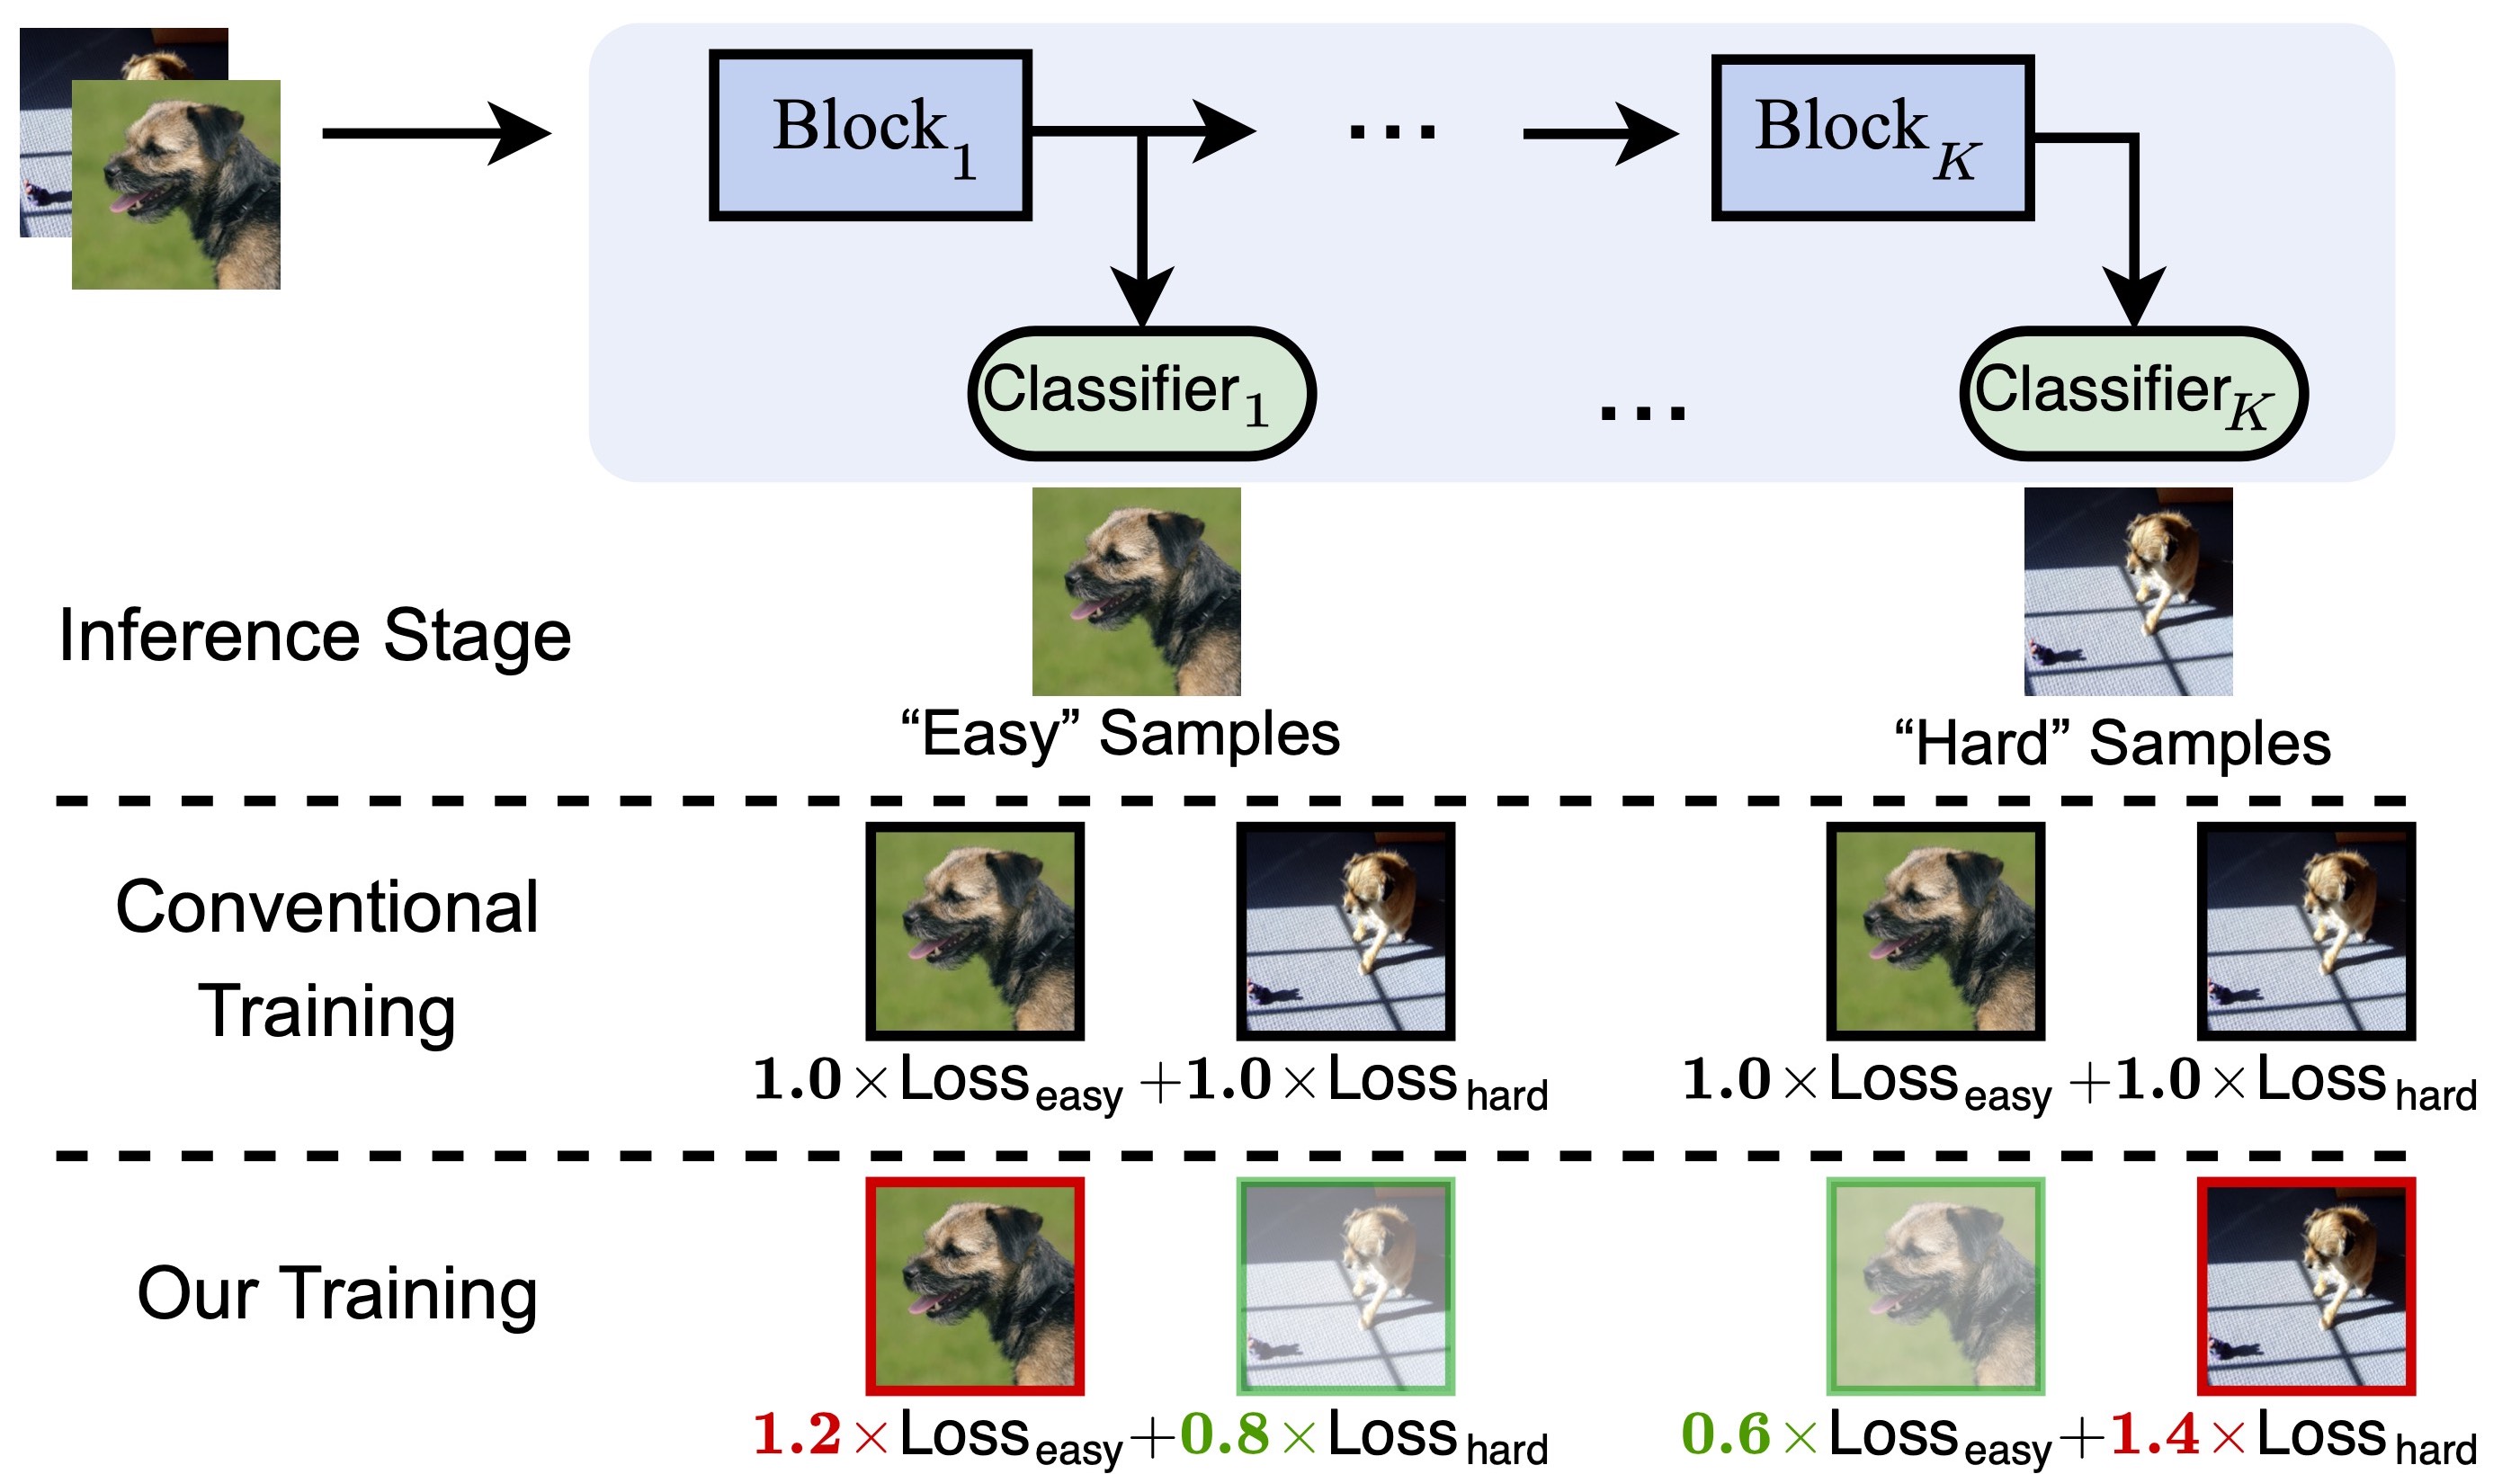
Learning to Weight Samples for Dynamic Early-exiting Networks

Yizeng Han*, Yifan Pu*, Zihang Lai, Chaofei Wang, Shiji Song, Junfen Cao, Wenhui Huang, Chao Deng, Gao Huang
LASNet
NeurIPS, 2022

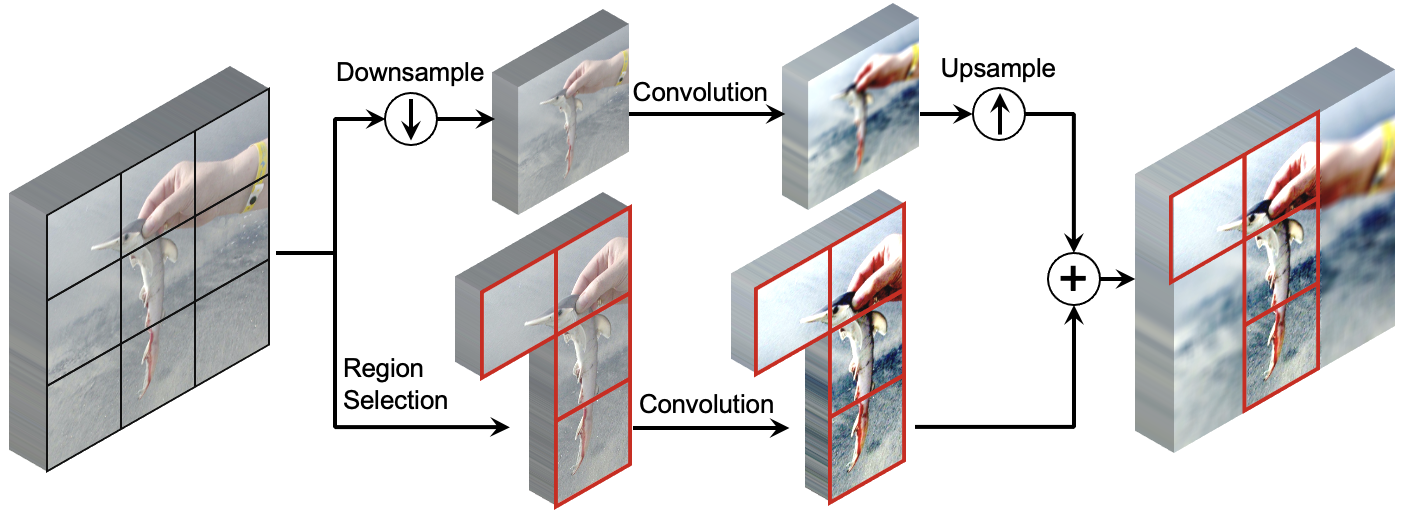
Latency-aware Spatial-wise Dynamic Networks

Yizeng Han*, Zhihang Yuan*, Yifan Pu*, Chenhao Xue, Shiji Song, Guangyu Sun, Gao Huang
RANet
CVPR, 2020

Resolution Adaptive Networks for Efficient Inference

Le Yang*, Yizeng Han*, Xi Chen*, Shiji Song, Jifeng Dai, Gao Huang
SAR
IEEE TIP, 2021

Spatially Adaptive Feature Refinement for Efficient Inference

Yizeng Han, Gao Huang, Shiji Song, Le Yang, Yitian Zhang, Haojun Jiang
SimPro
ICML, 2024

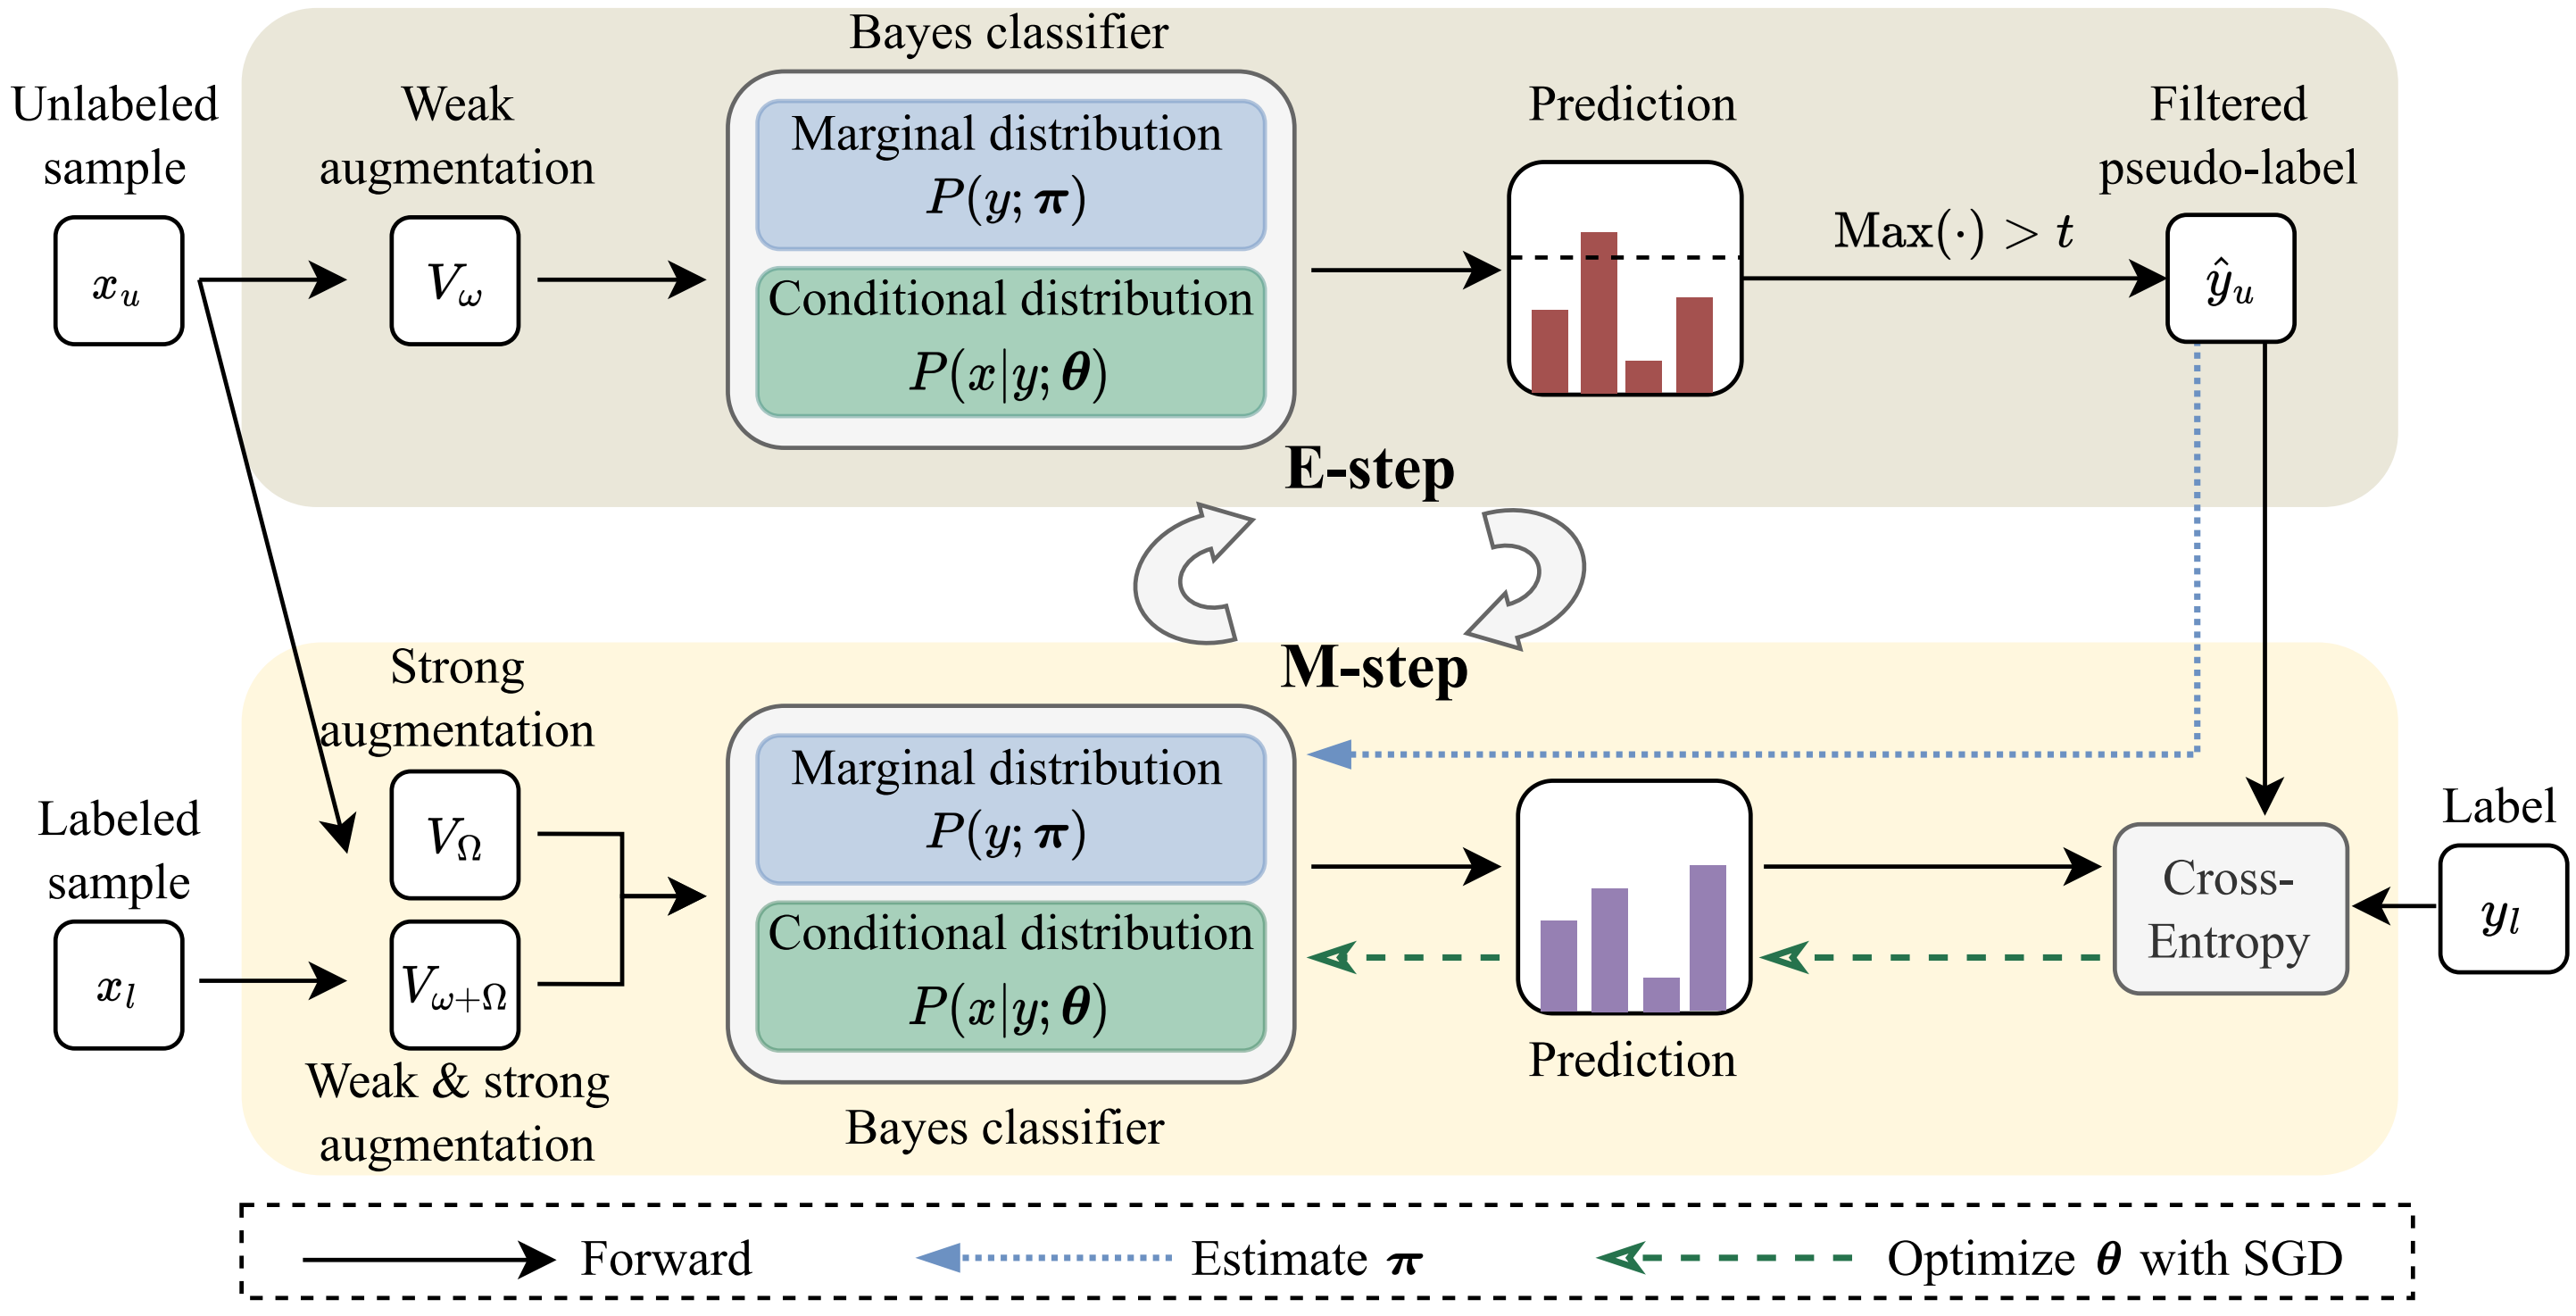
SimPro: A Simple Probabilistic Framework Towards Realistic Long-Tailed Semi-Supervised Learning

Chaoqun Du*, Yizeng Han*, Gao Huang
LearnableISDA
IEEE TIP, 2023

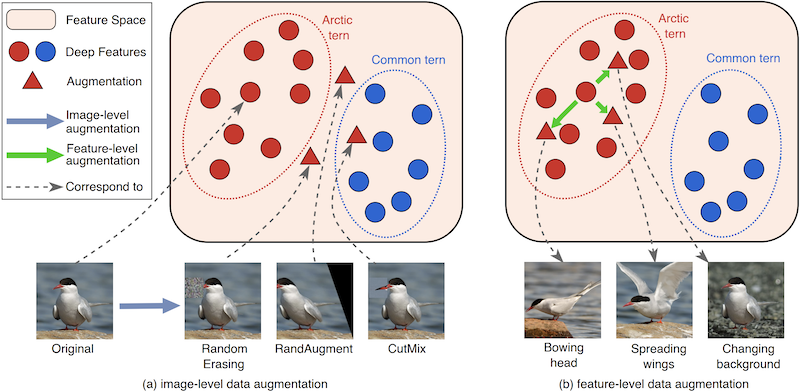
Fine-grained Recognition with Learnable Semantic Data Augmentation

Yifan Pu*, Yizeng Han*, Yulin Wang, Junlan Feng, Chao Deng, Gao Huang

Earlier updates

News archive
  • 12/2025 We release a technical report and codebase for few-step text-to-image distillation.
  • 09/2025 AdaptiveNN is accepted by Nature Machine Intelligence.
  • 09/2025 FPSAttention is selected as a NeurIPS 2025 Highlight.
  • 02/2025 SGL is accepted at CVPR 2025.
  • 01/2025 DyDiT is accepted at ICLR 2025.
  • 11/2024 First Prize of CSIG Natural Science Award (中国图象图形学会自然科学奖一等奖).
  • 09/2024 Five works are accepted at NeurIPS 2024.
  • 07/2024 Four works are accepted at ECCV 2024.
  • 06/2024 Awarded by Outstanding Graduate of Tsinghua University, Outstanding Doctoral Dissertation, and Outstanding Graduate of Beijing.
  • 05/2024 Our work (EfficientTrain++) is accepted at TPAMI!
  • 05/2024 Our work (SimPro) is accepted at ICML 2024.
  • 04/2024 Our work (LAUDNet) is accepted at TPAMI!
  • 02/2024 Two works (GSVA and Mask Grounding) are accepted at CVPR 2024.
  • 12/2023 Our work (Learnable Semantic Data Augmentation) is accepted at TIP.
  • 10/2023 Awarded by Comprehensive Excellence Scholarship, Tsinghua University.
  • 07/2023 Three works are accepted by ICCV 2023.
  • 10/2022 Awarded by National Scholarship, Ministry of Education of China.